1 / 9
Use the arrows, swipe, or press ← → to move through the slides.
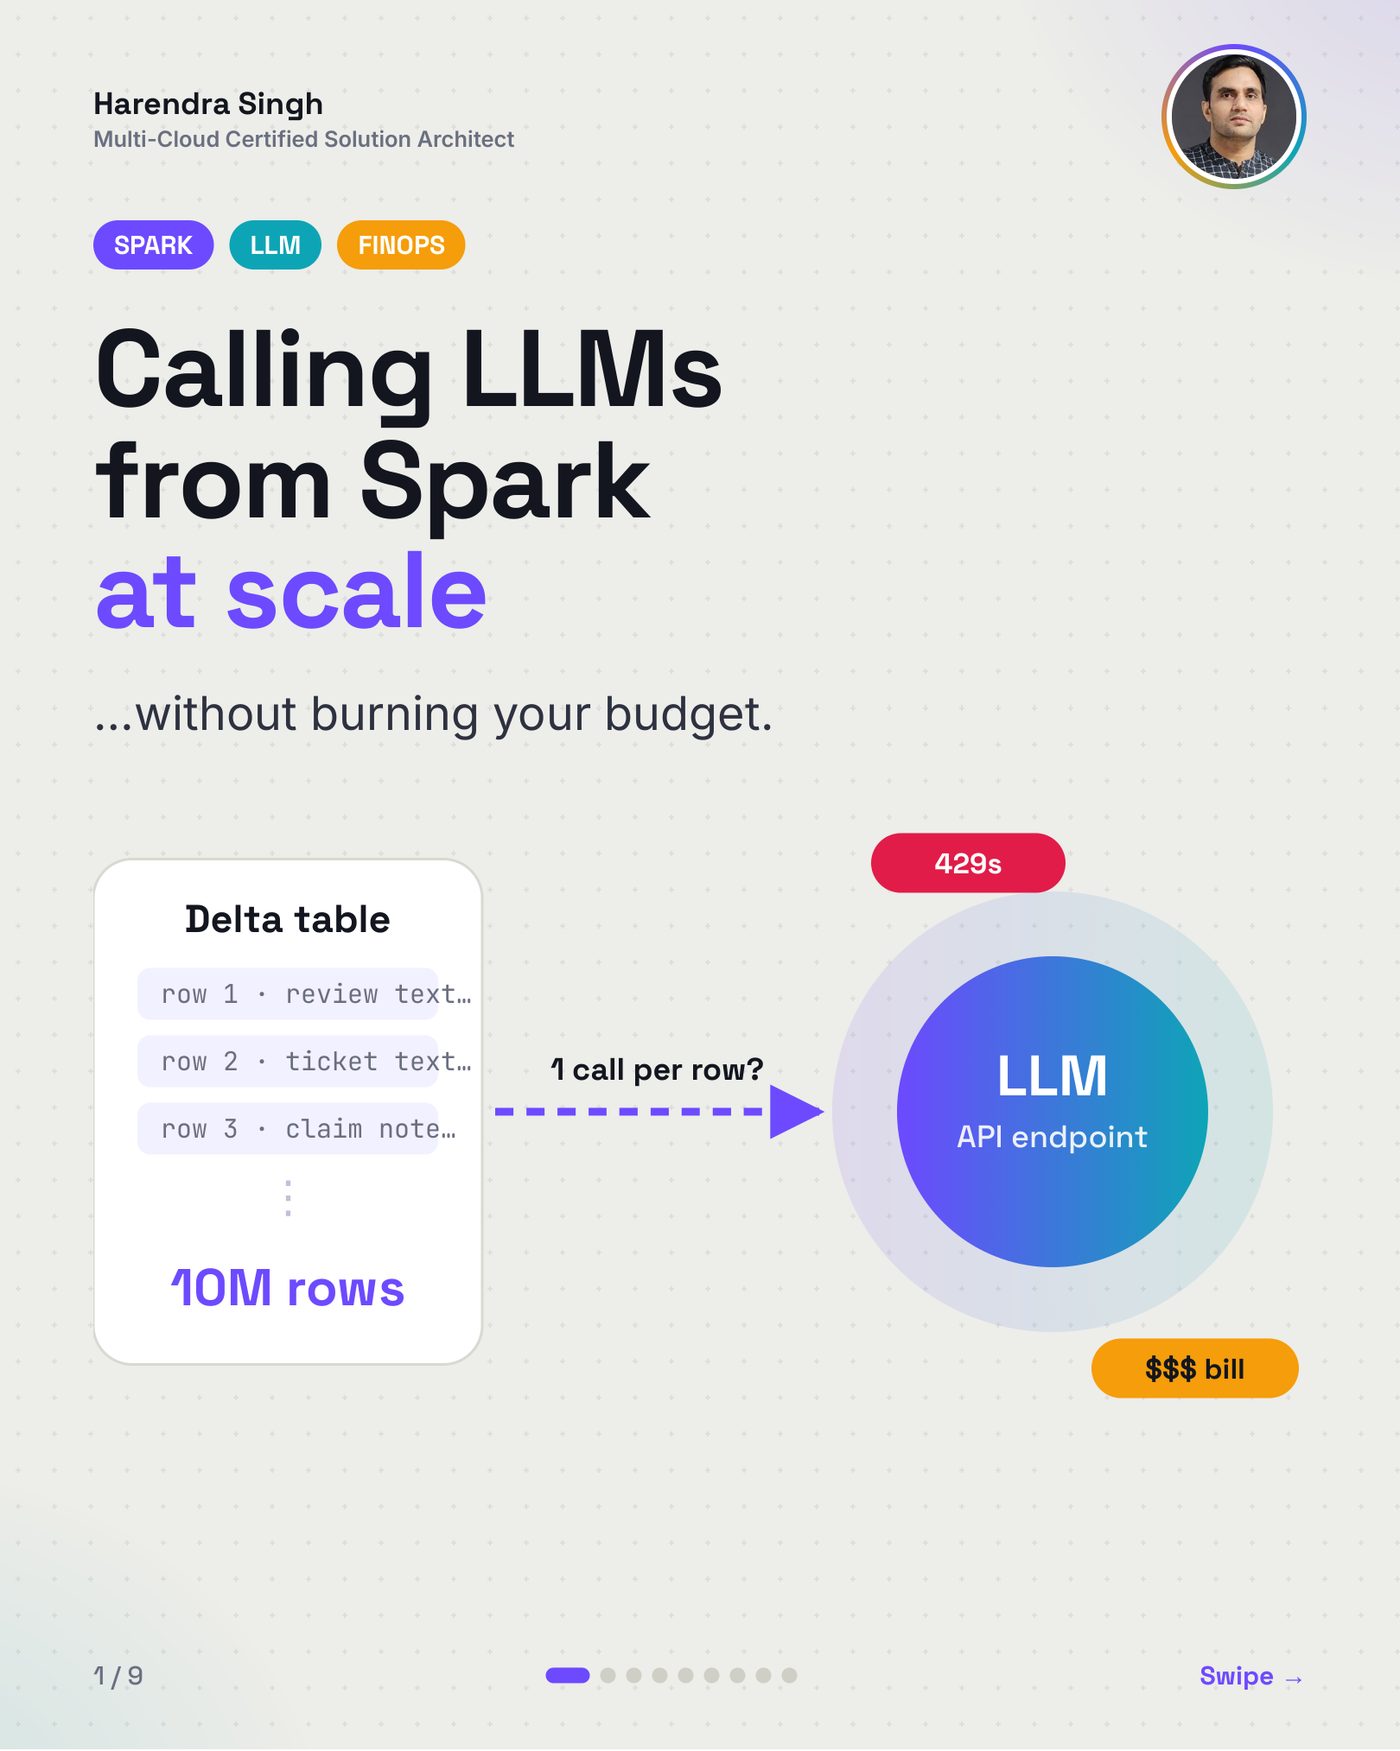
Calling LLMs from Spark at scale — without burning your budget
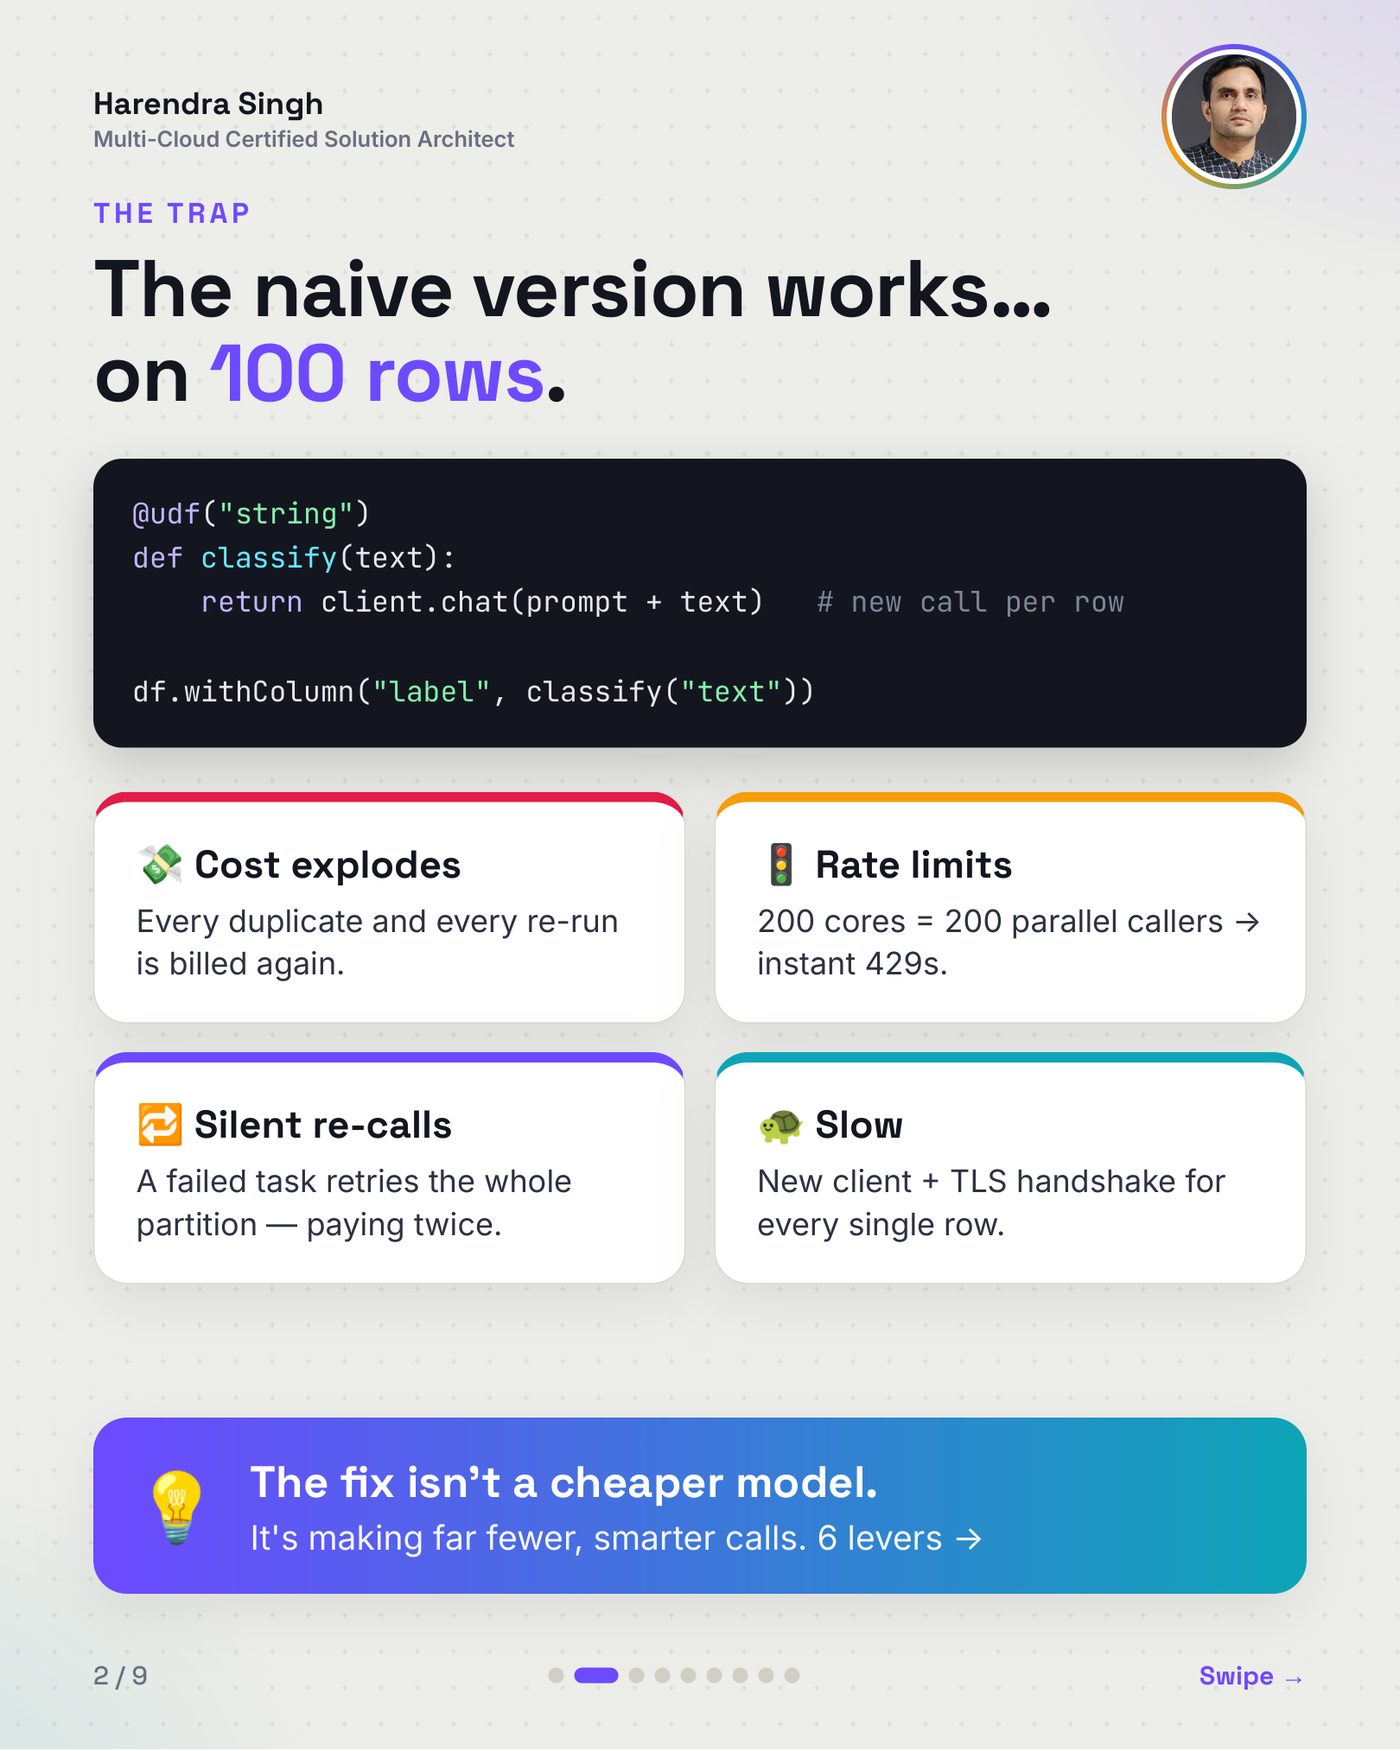
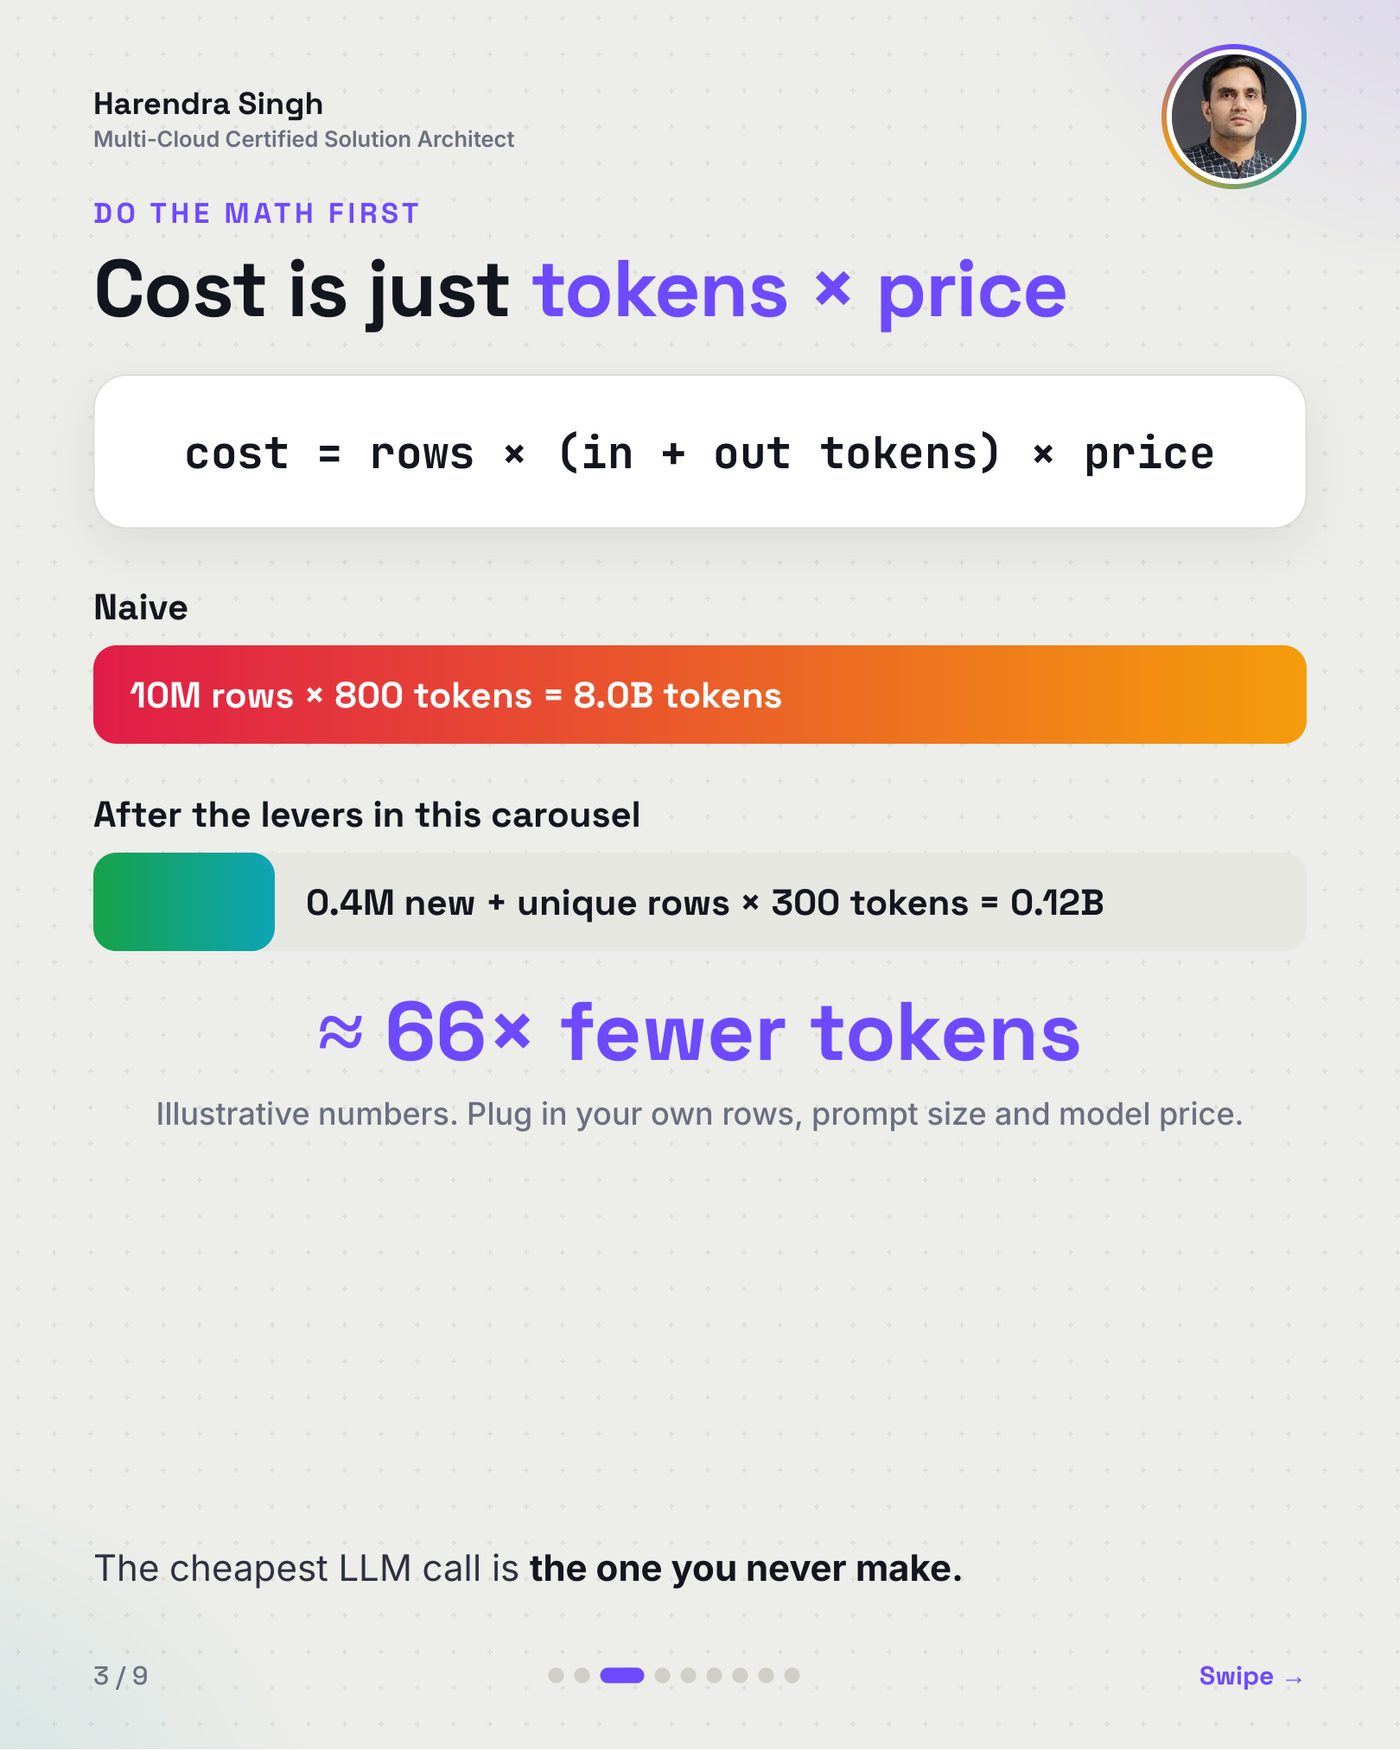
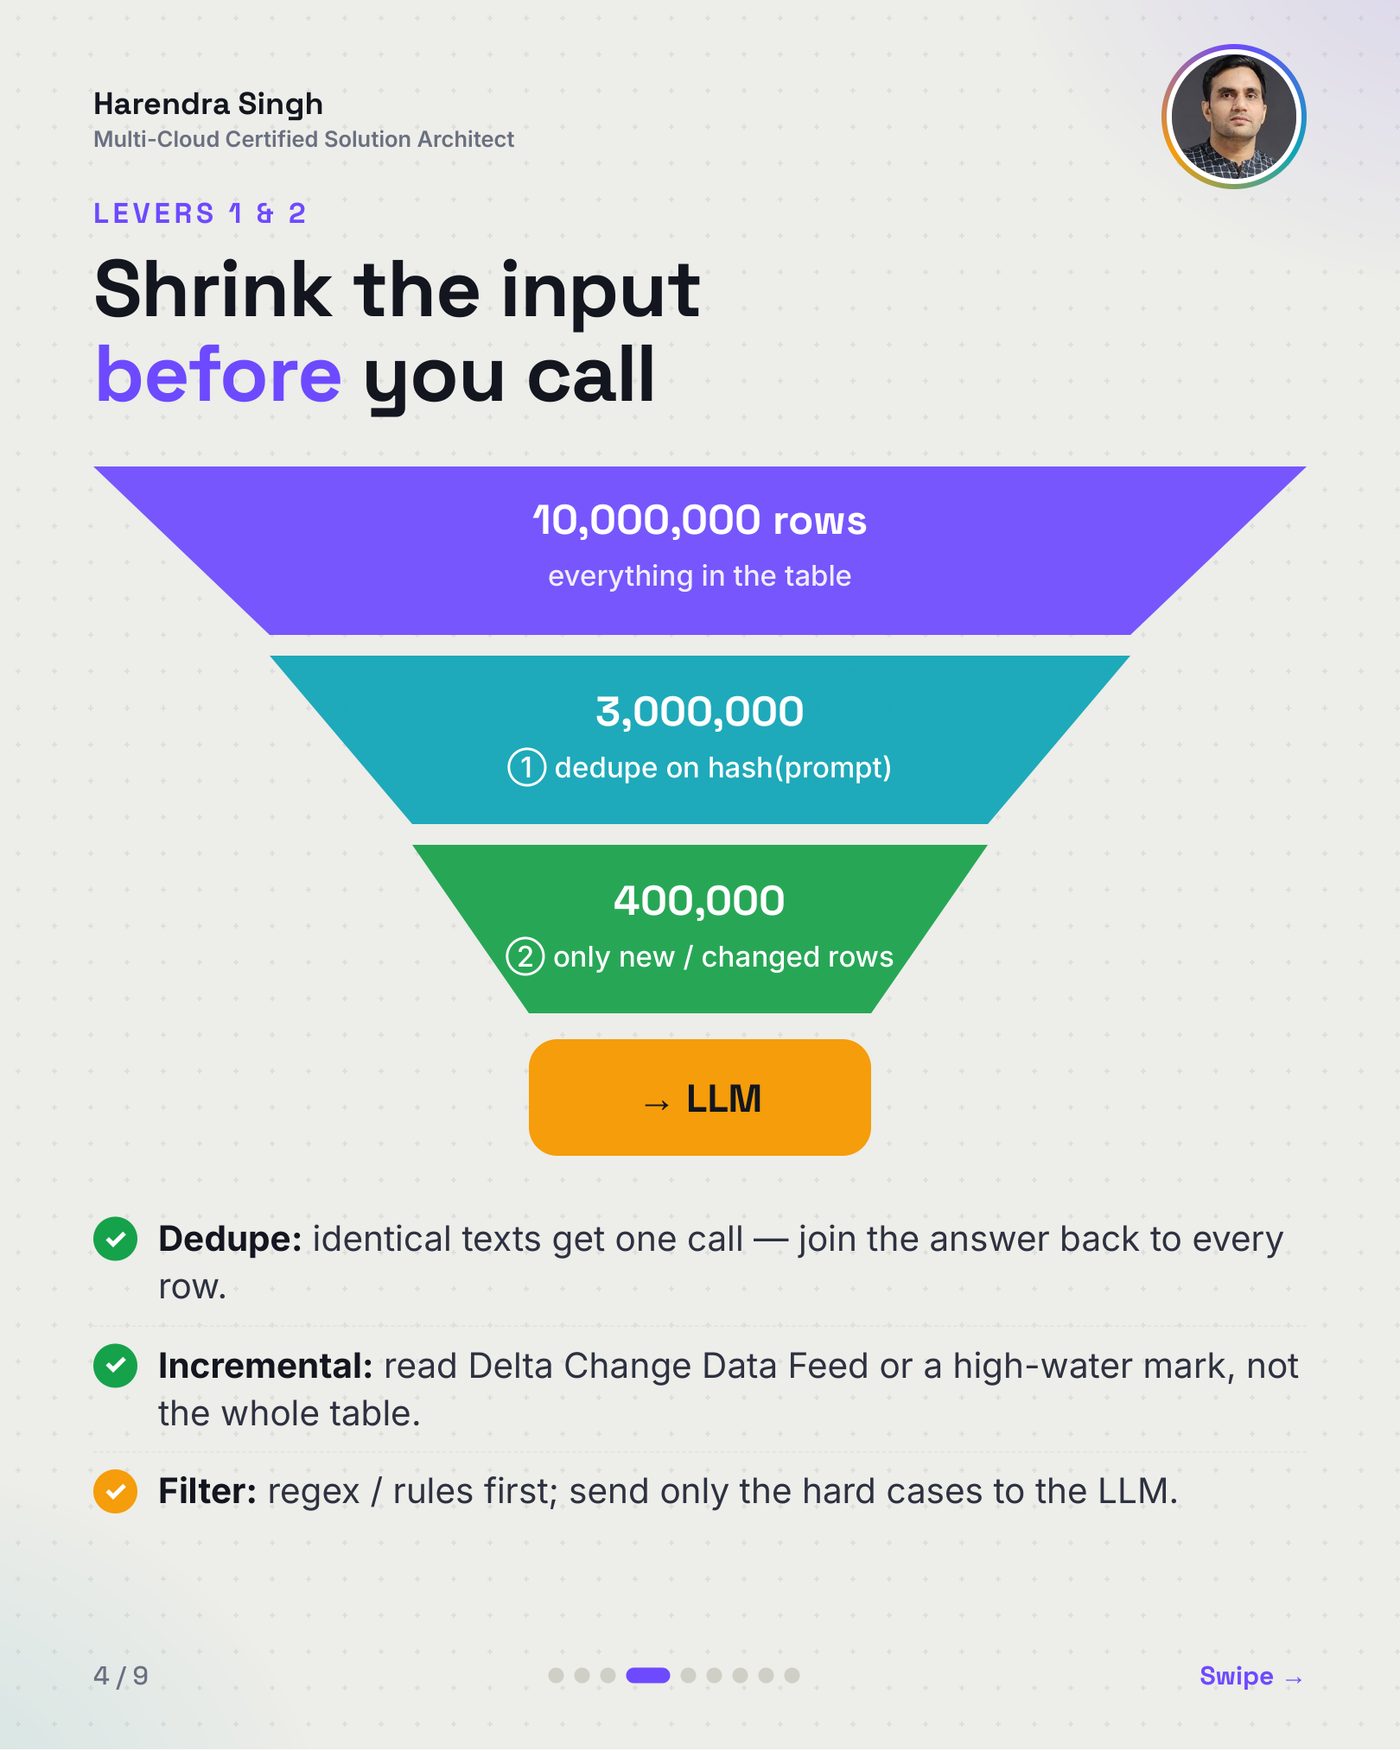
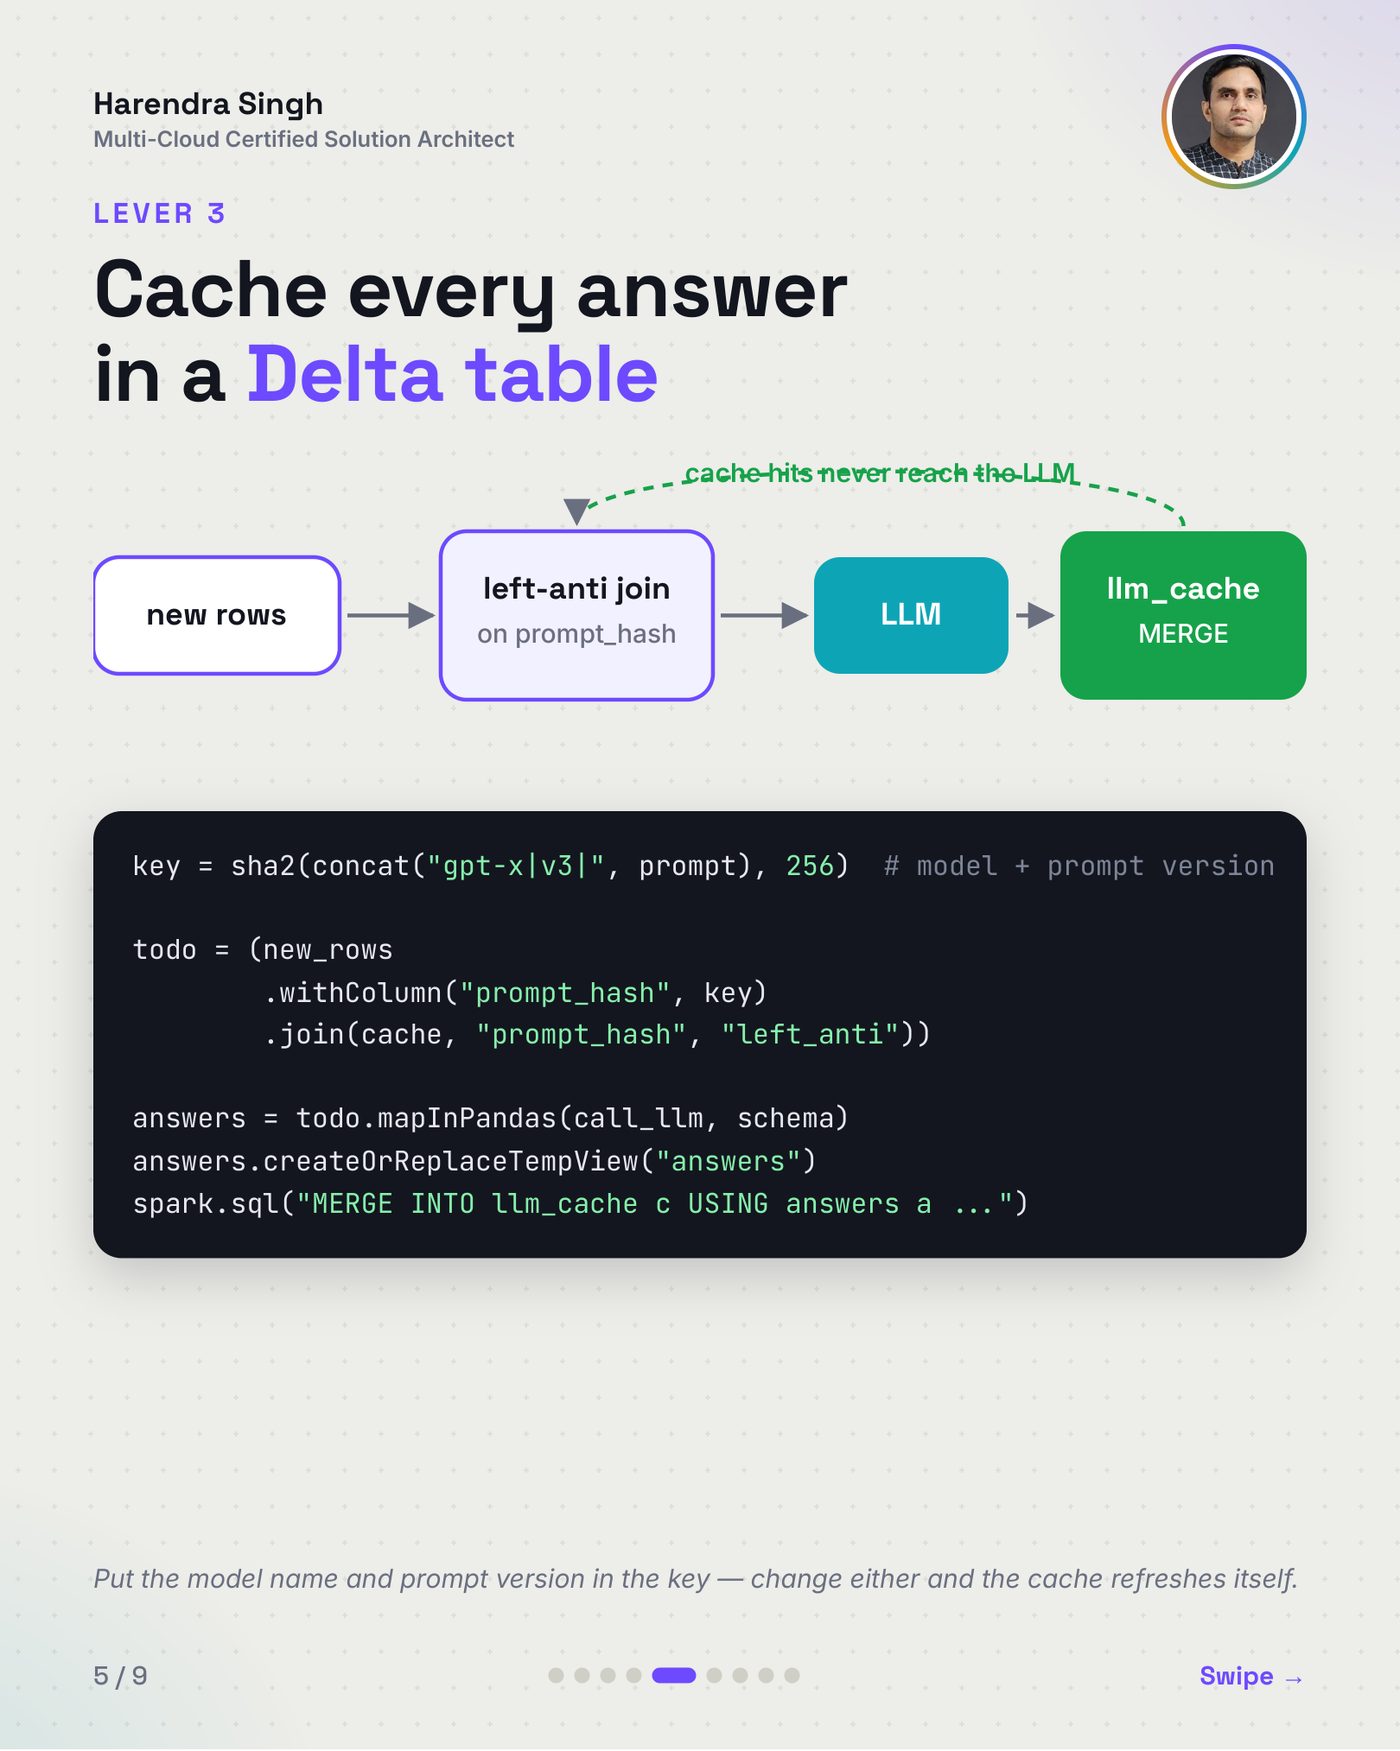
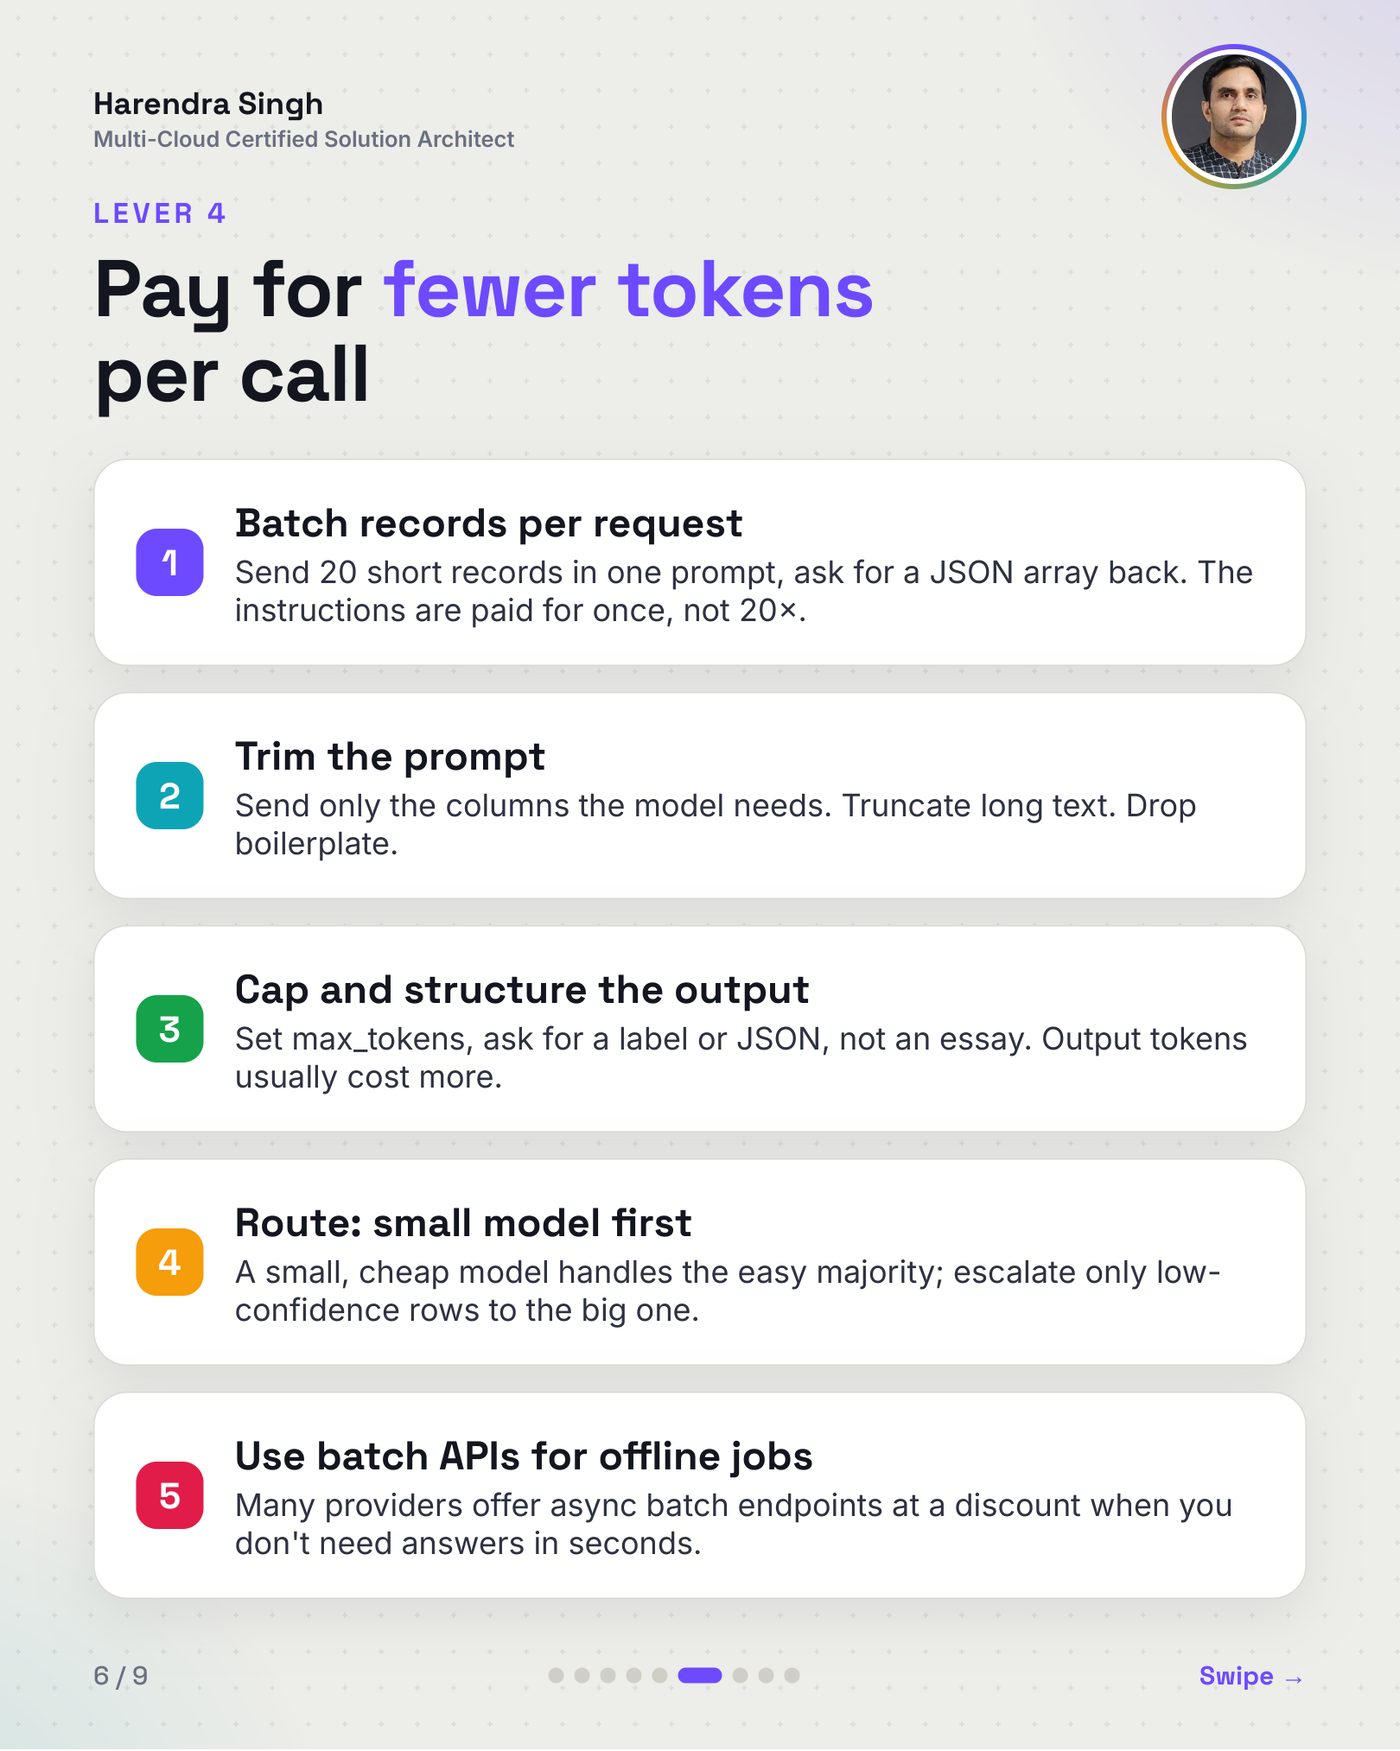
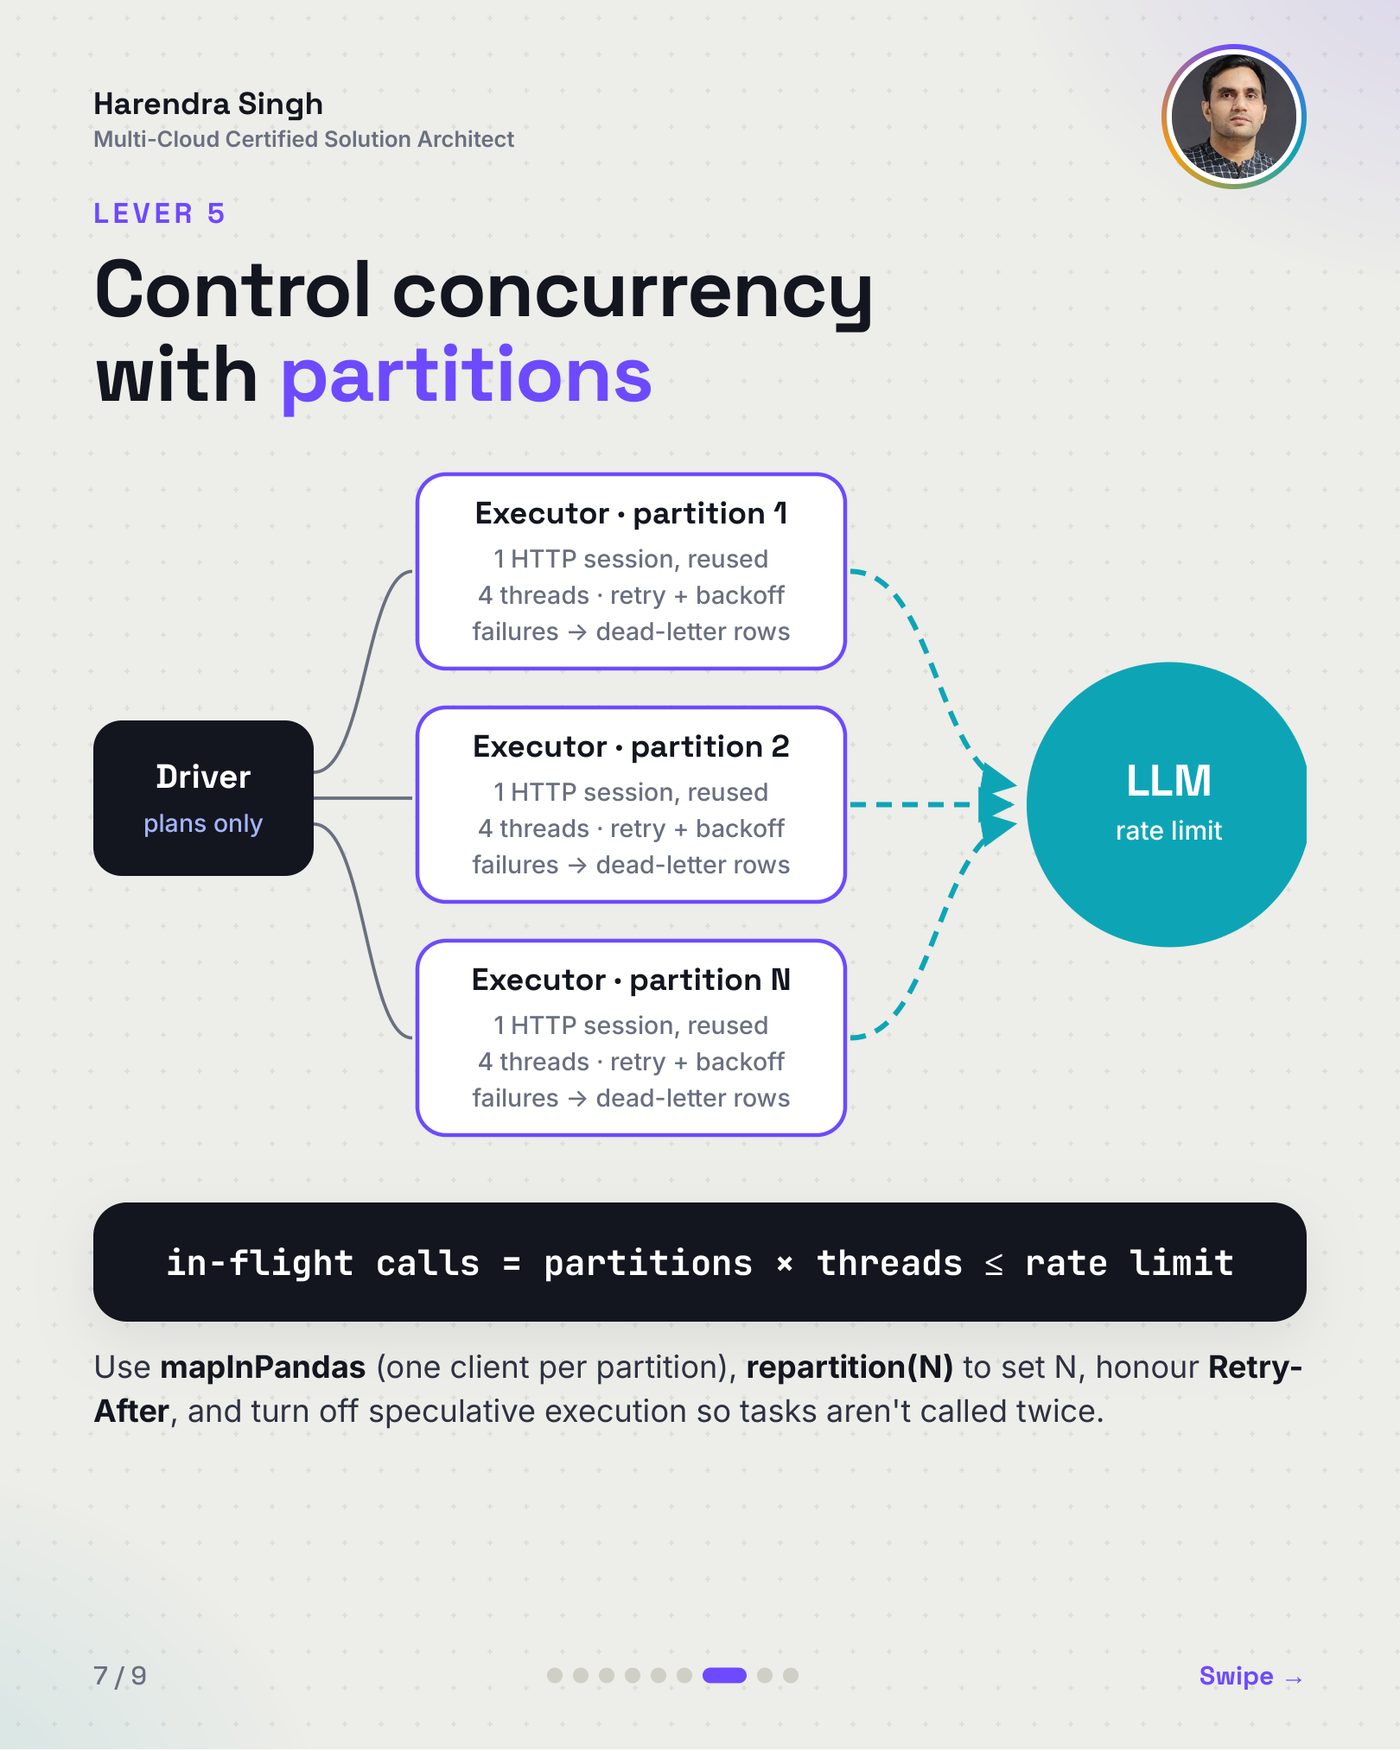
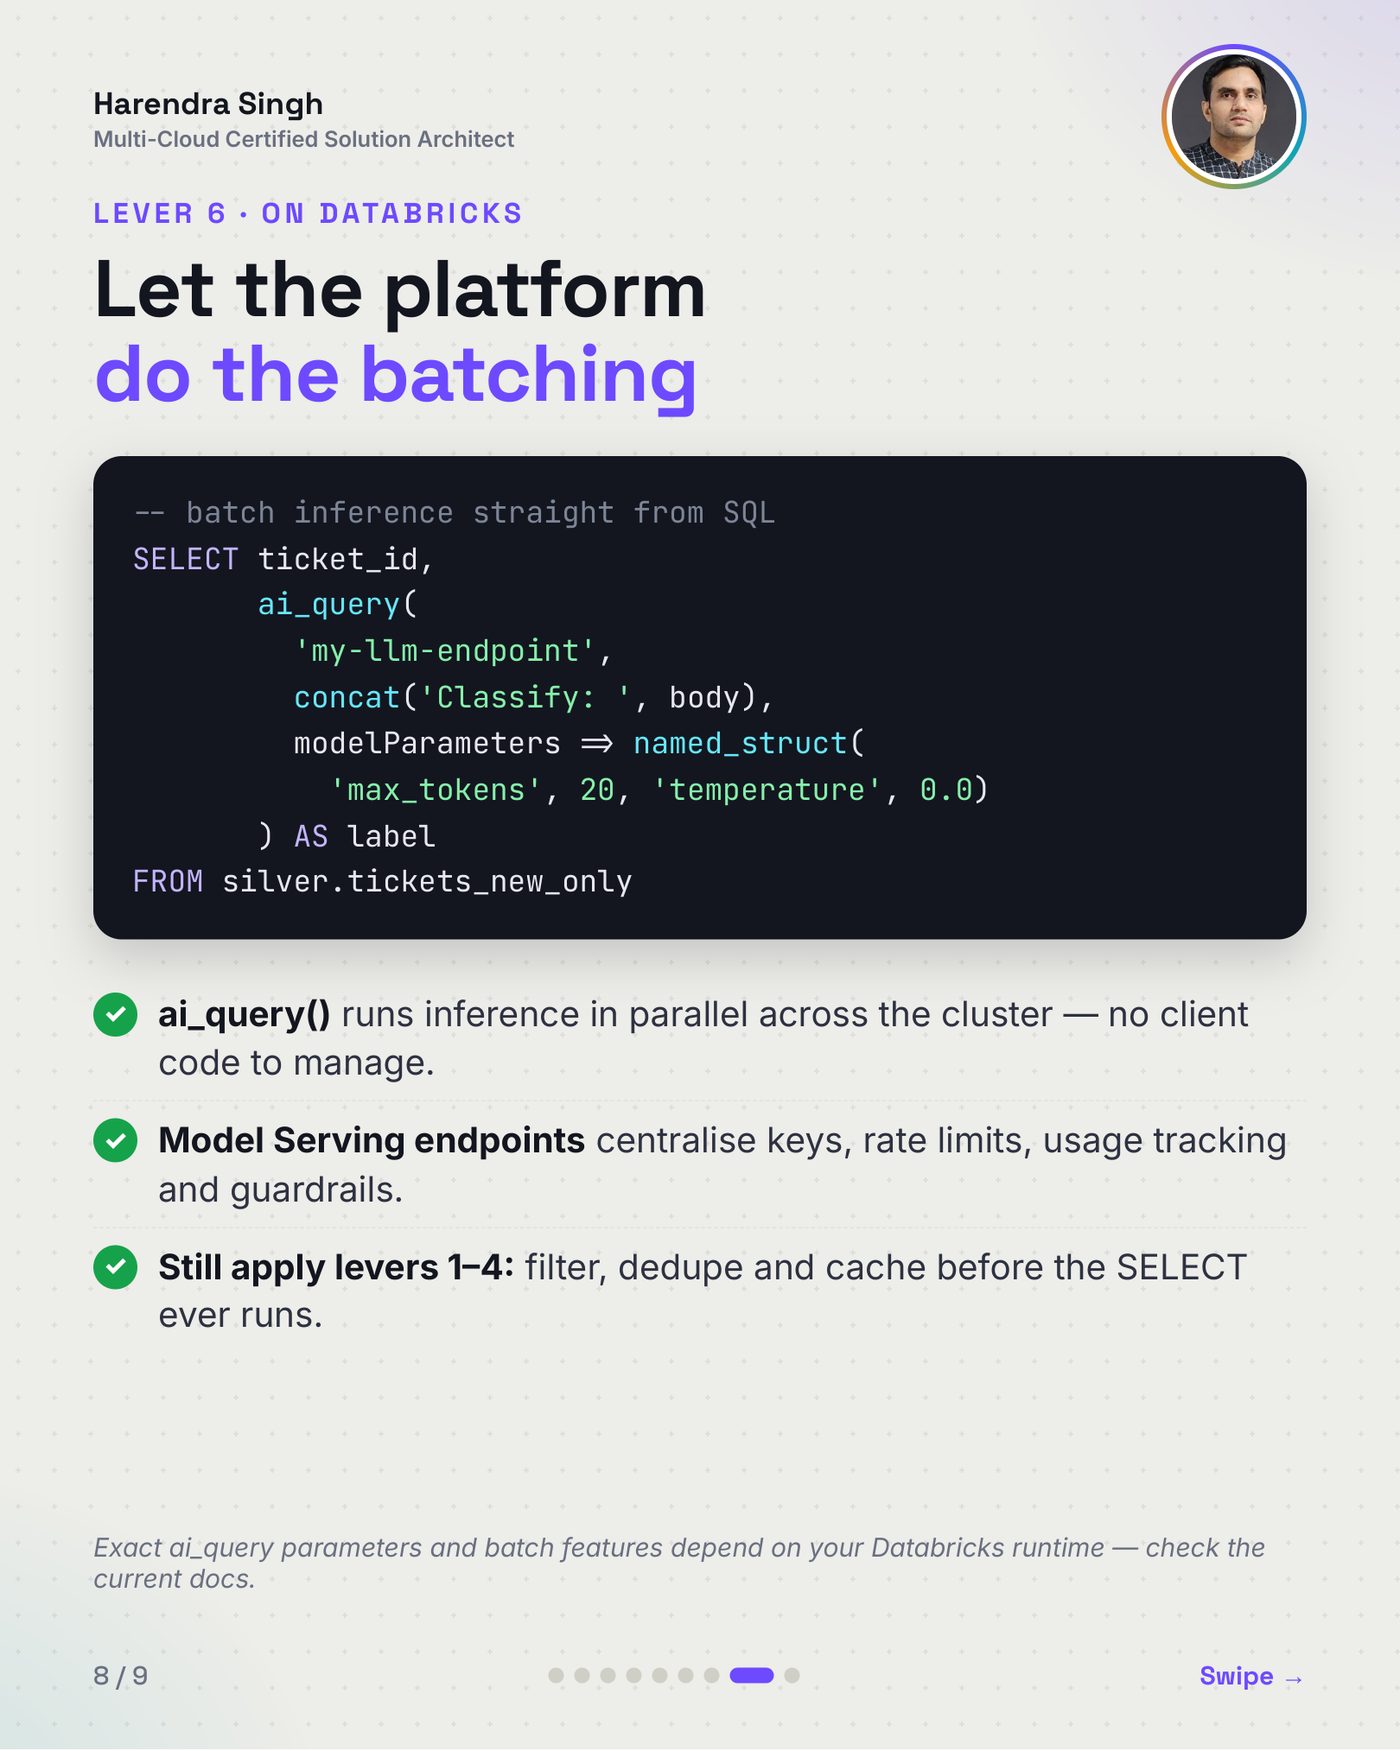
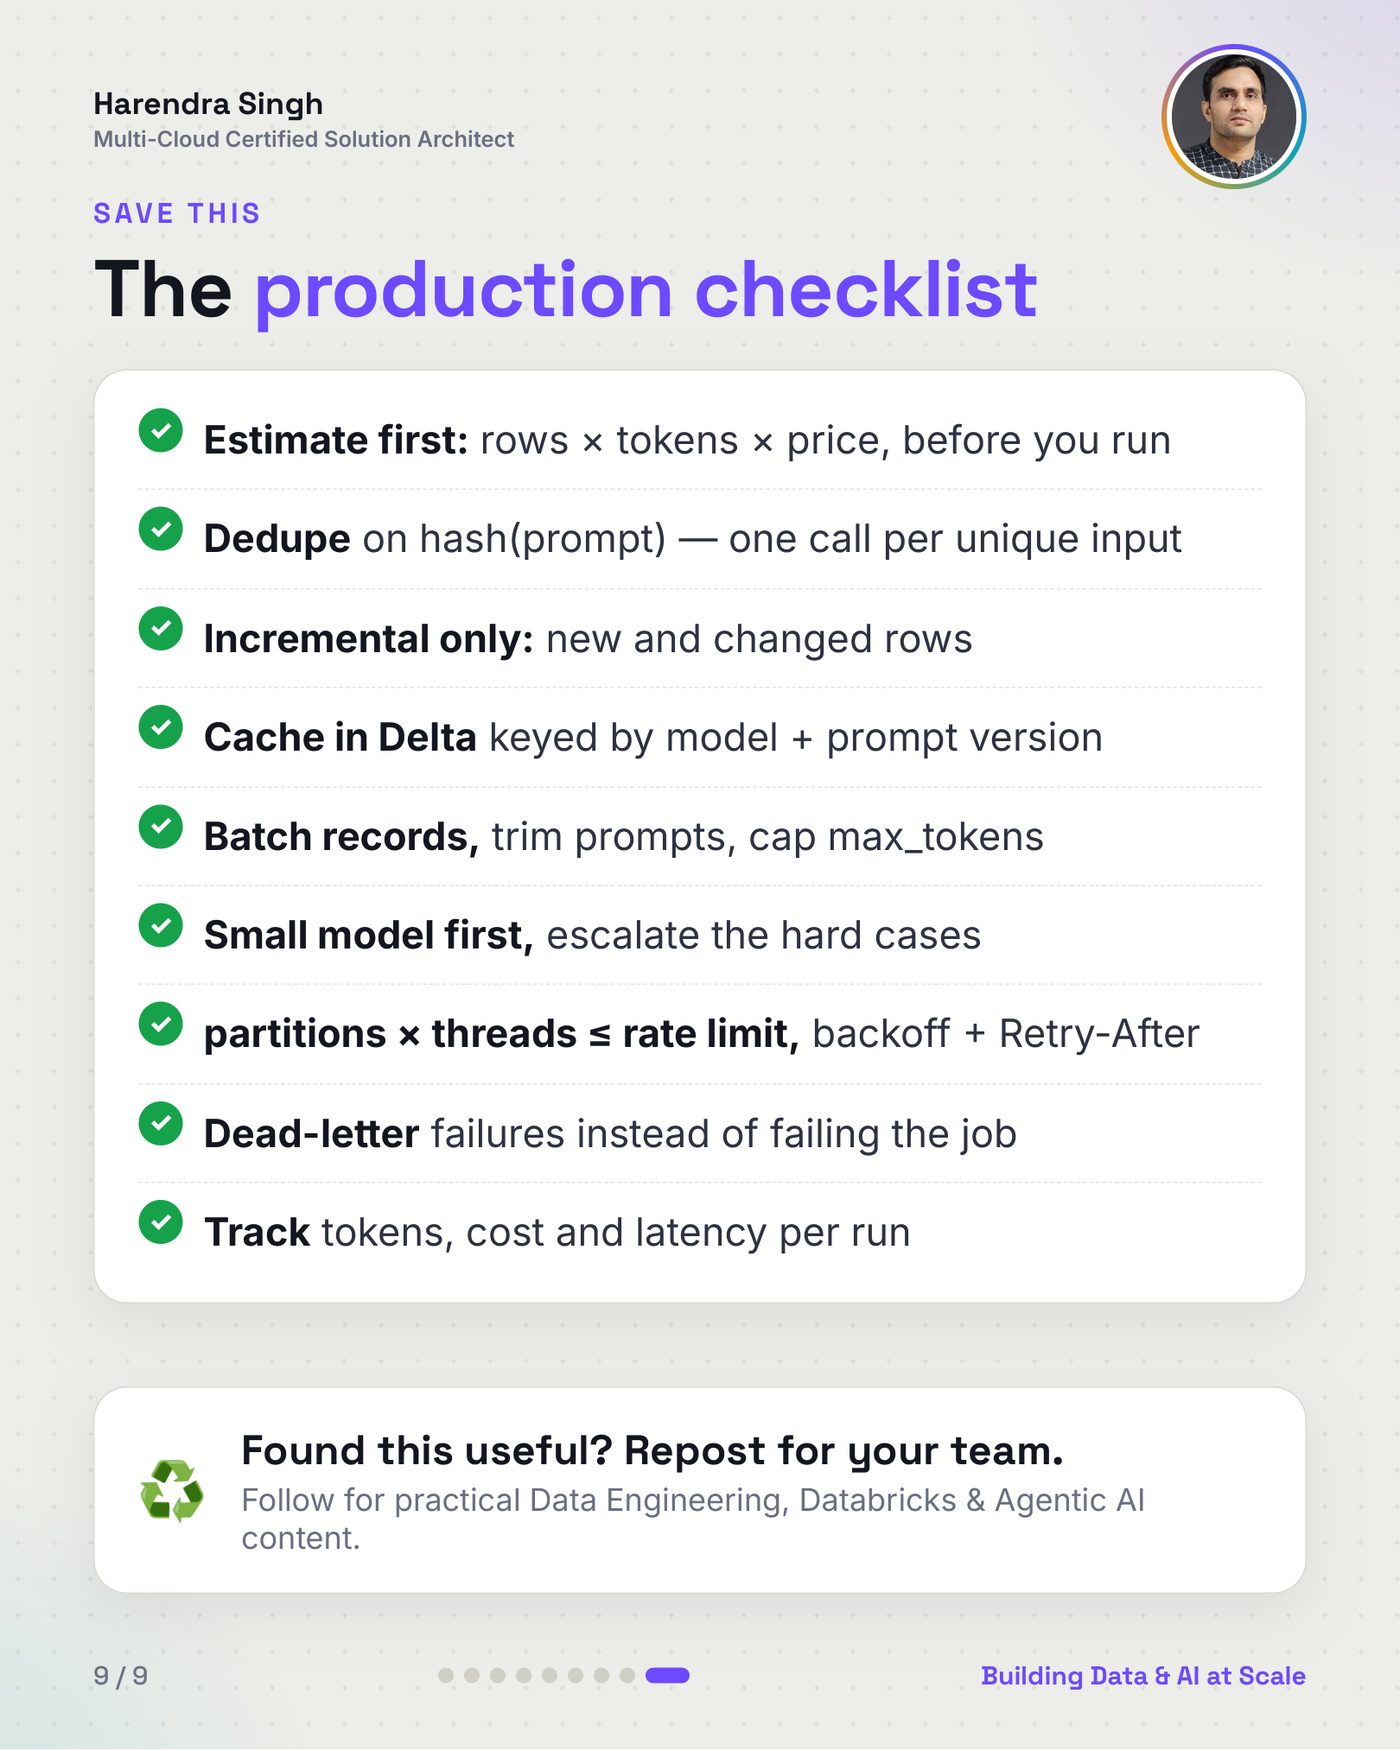
The naive UDF works on 100 rows and explodes on 10 million. Batching, caching, rate-limit handling and the FinOps view of LLM calls inside Spark.
The trade-off I'd flag
One API call per row is the most expensive line of code in modern data engineering. Batch at the partition level and cache by content hash.