1 / 10
Use the arrows, swipe, or press ← → to move through the slides.
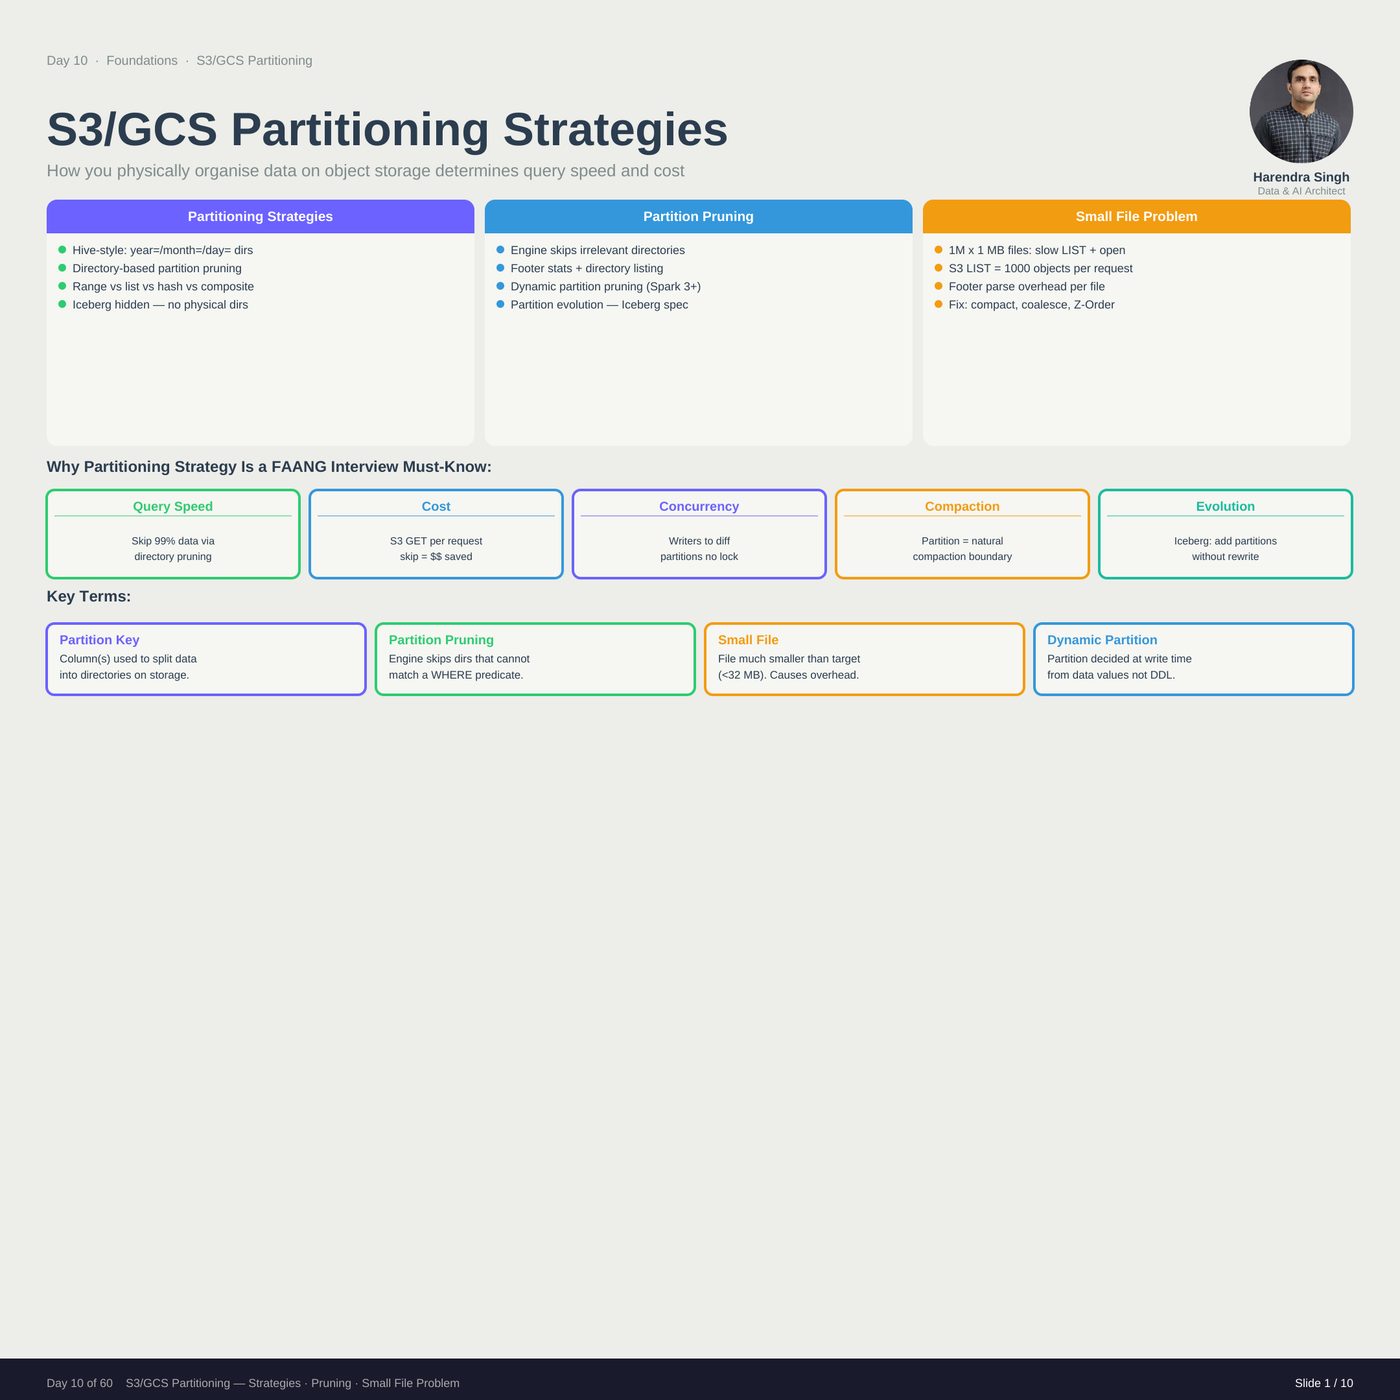
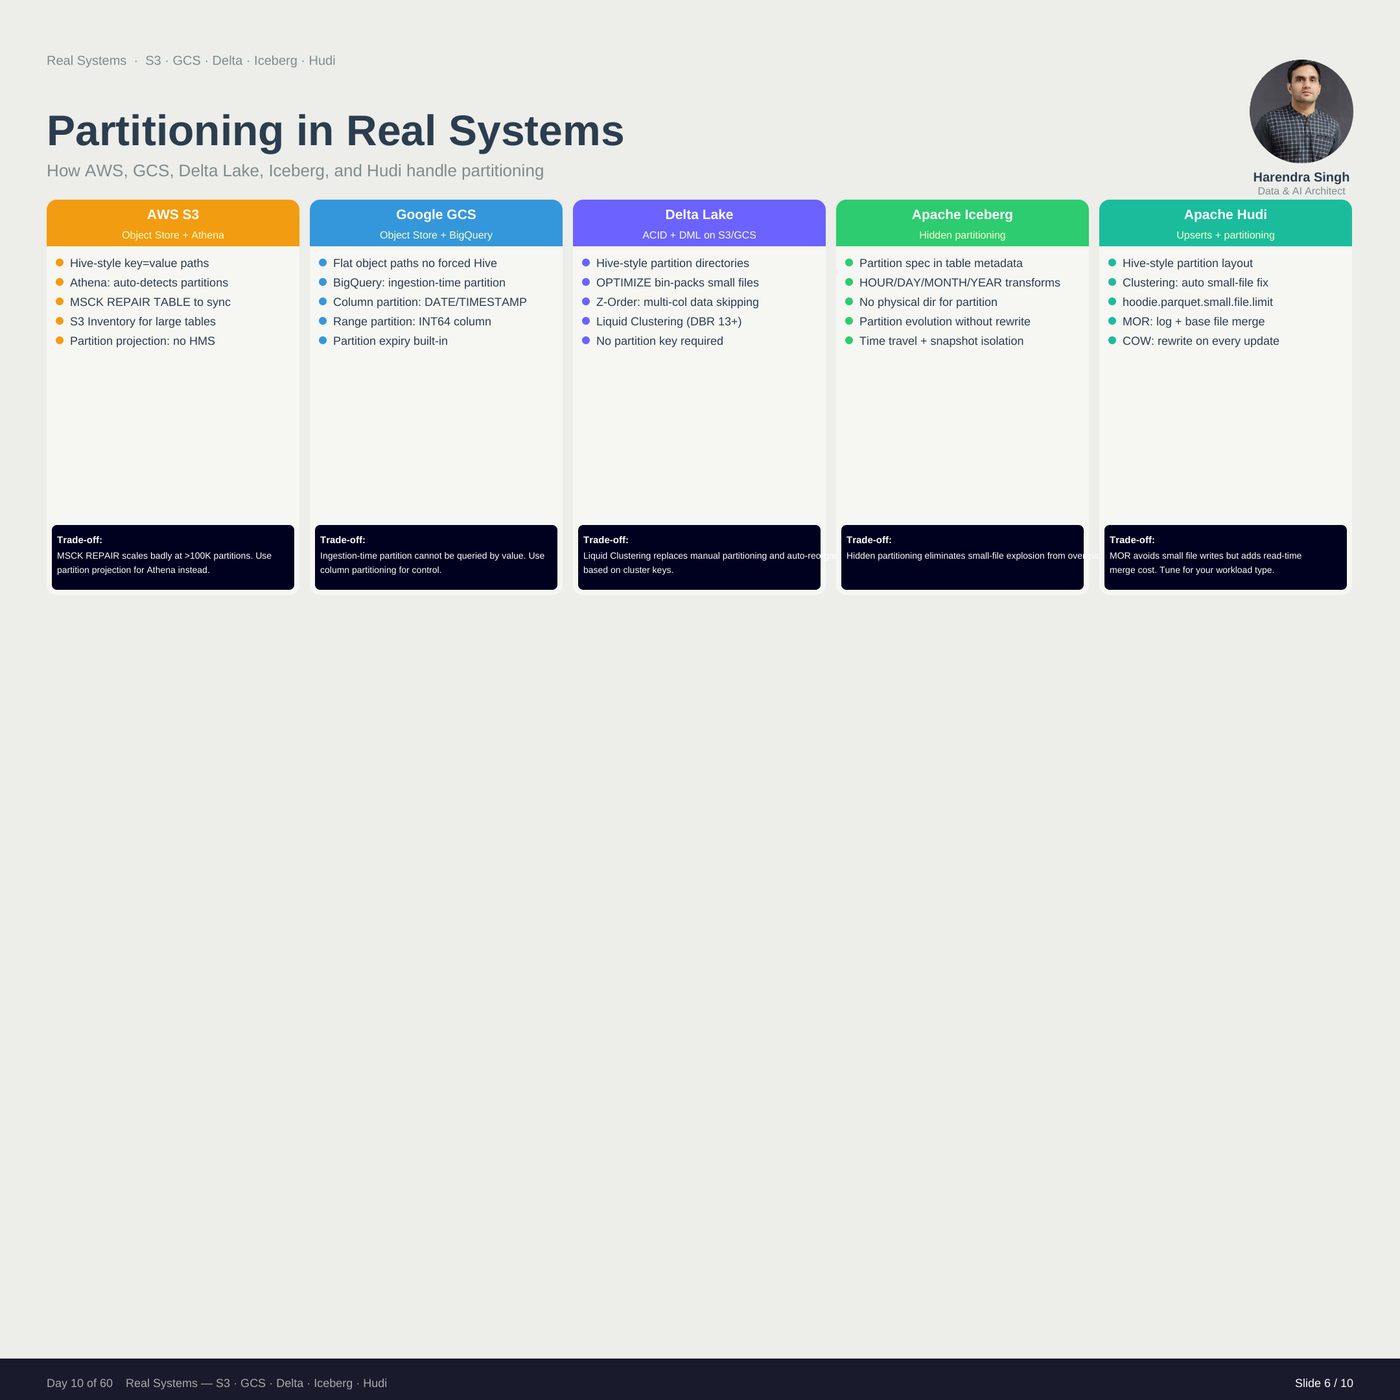
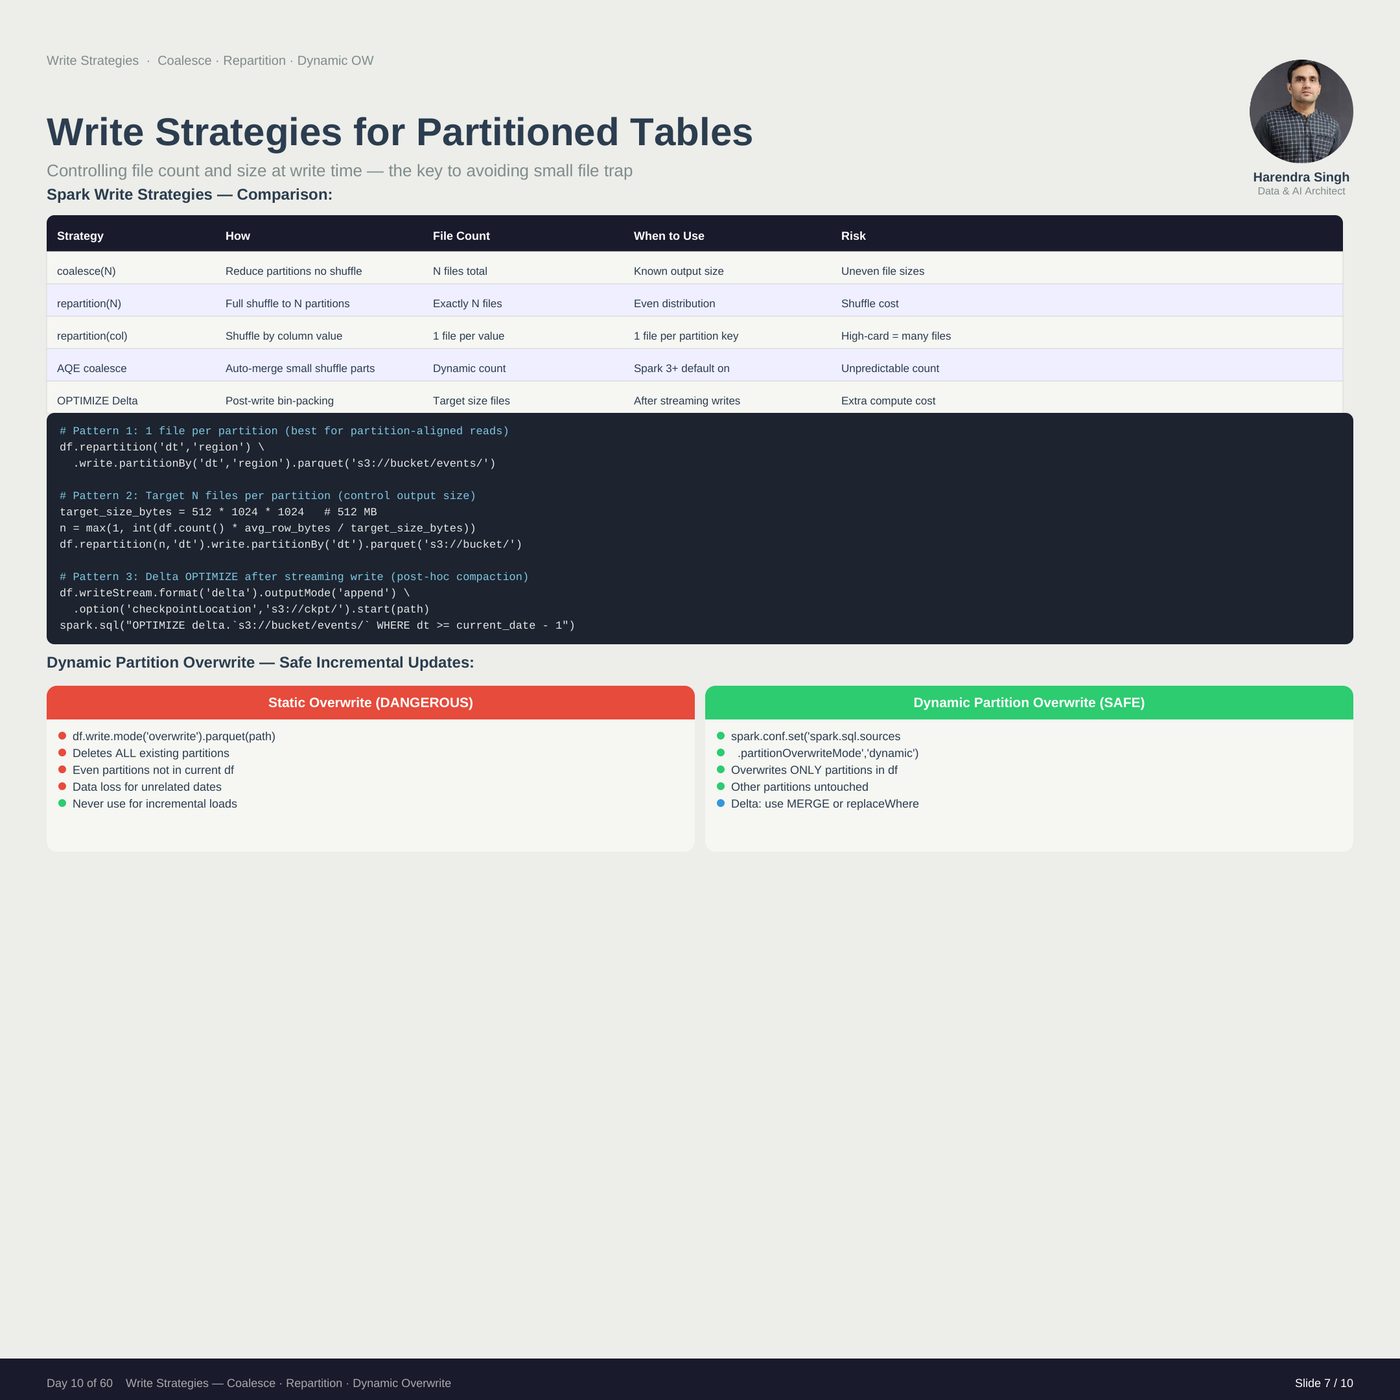
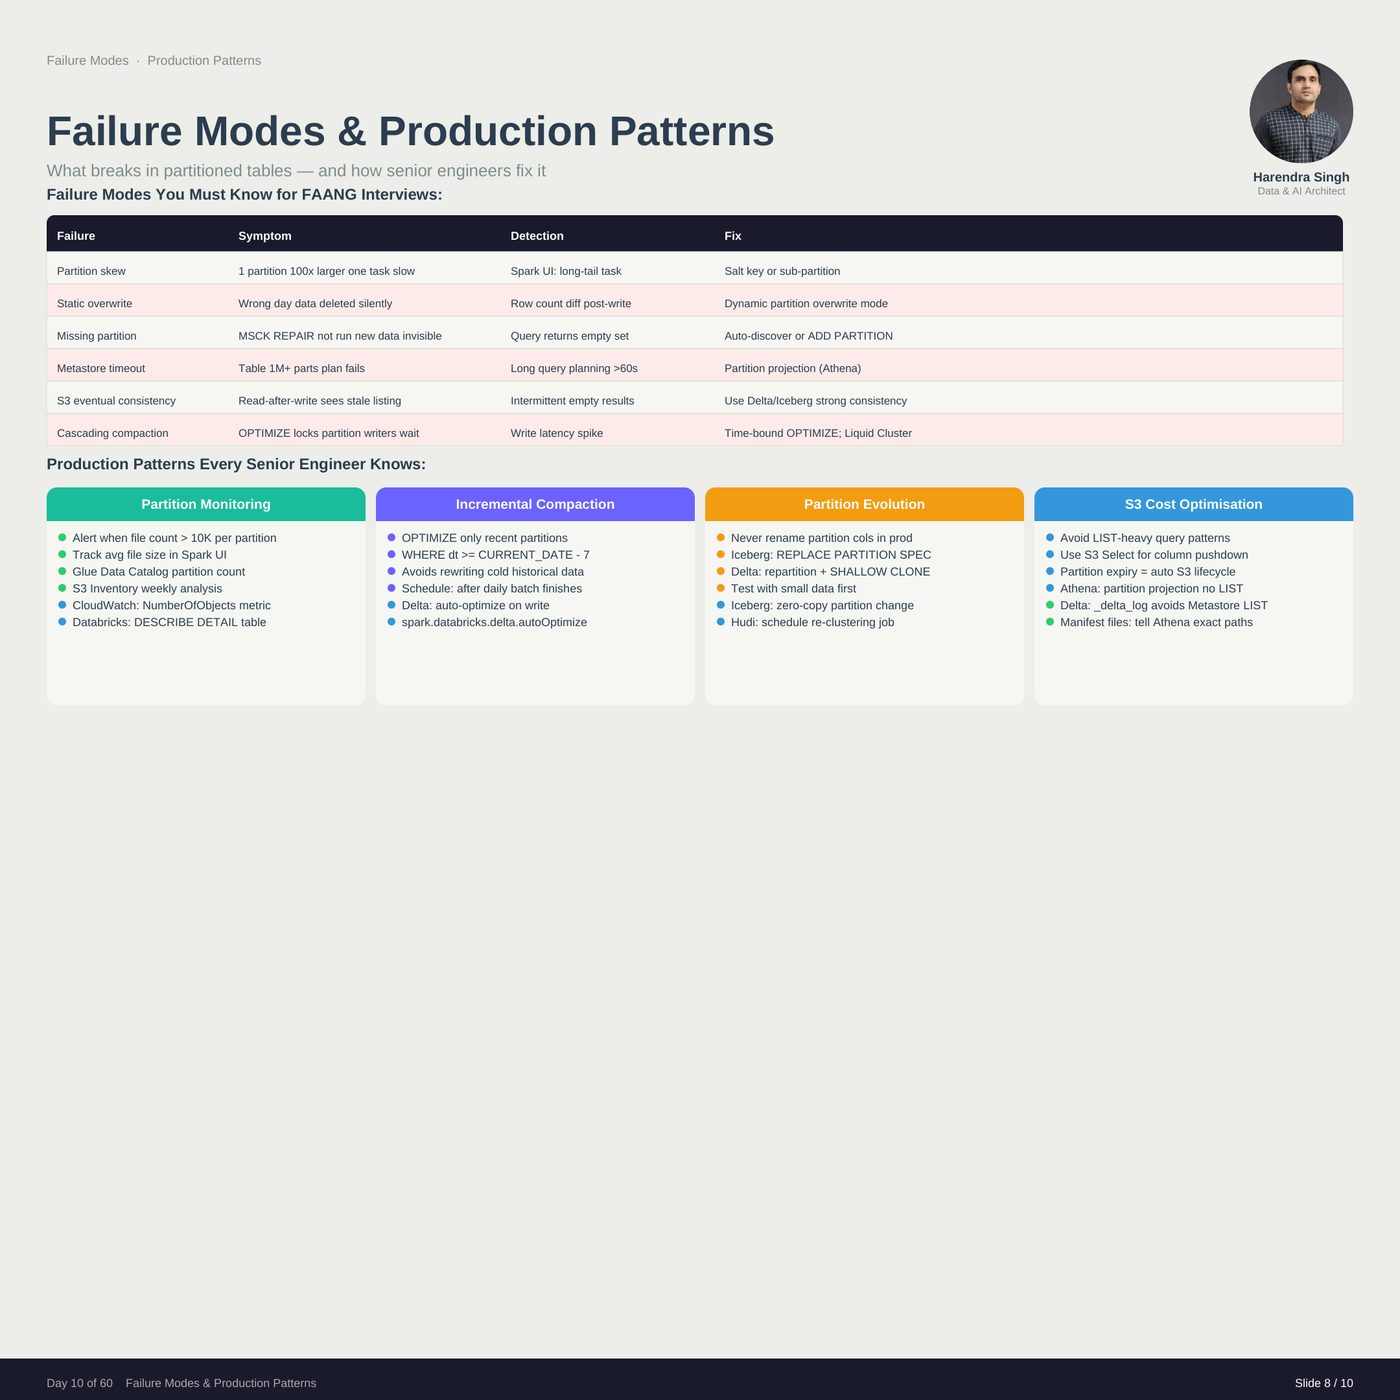
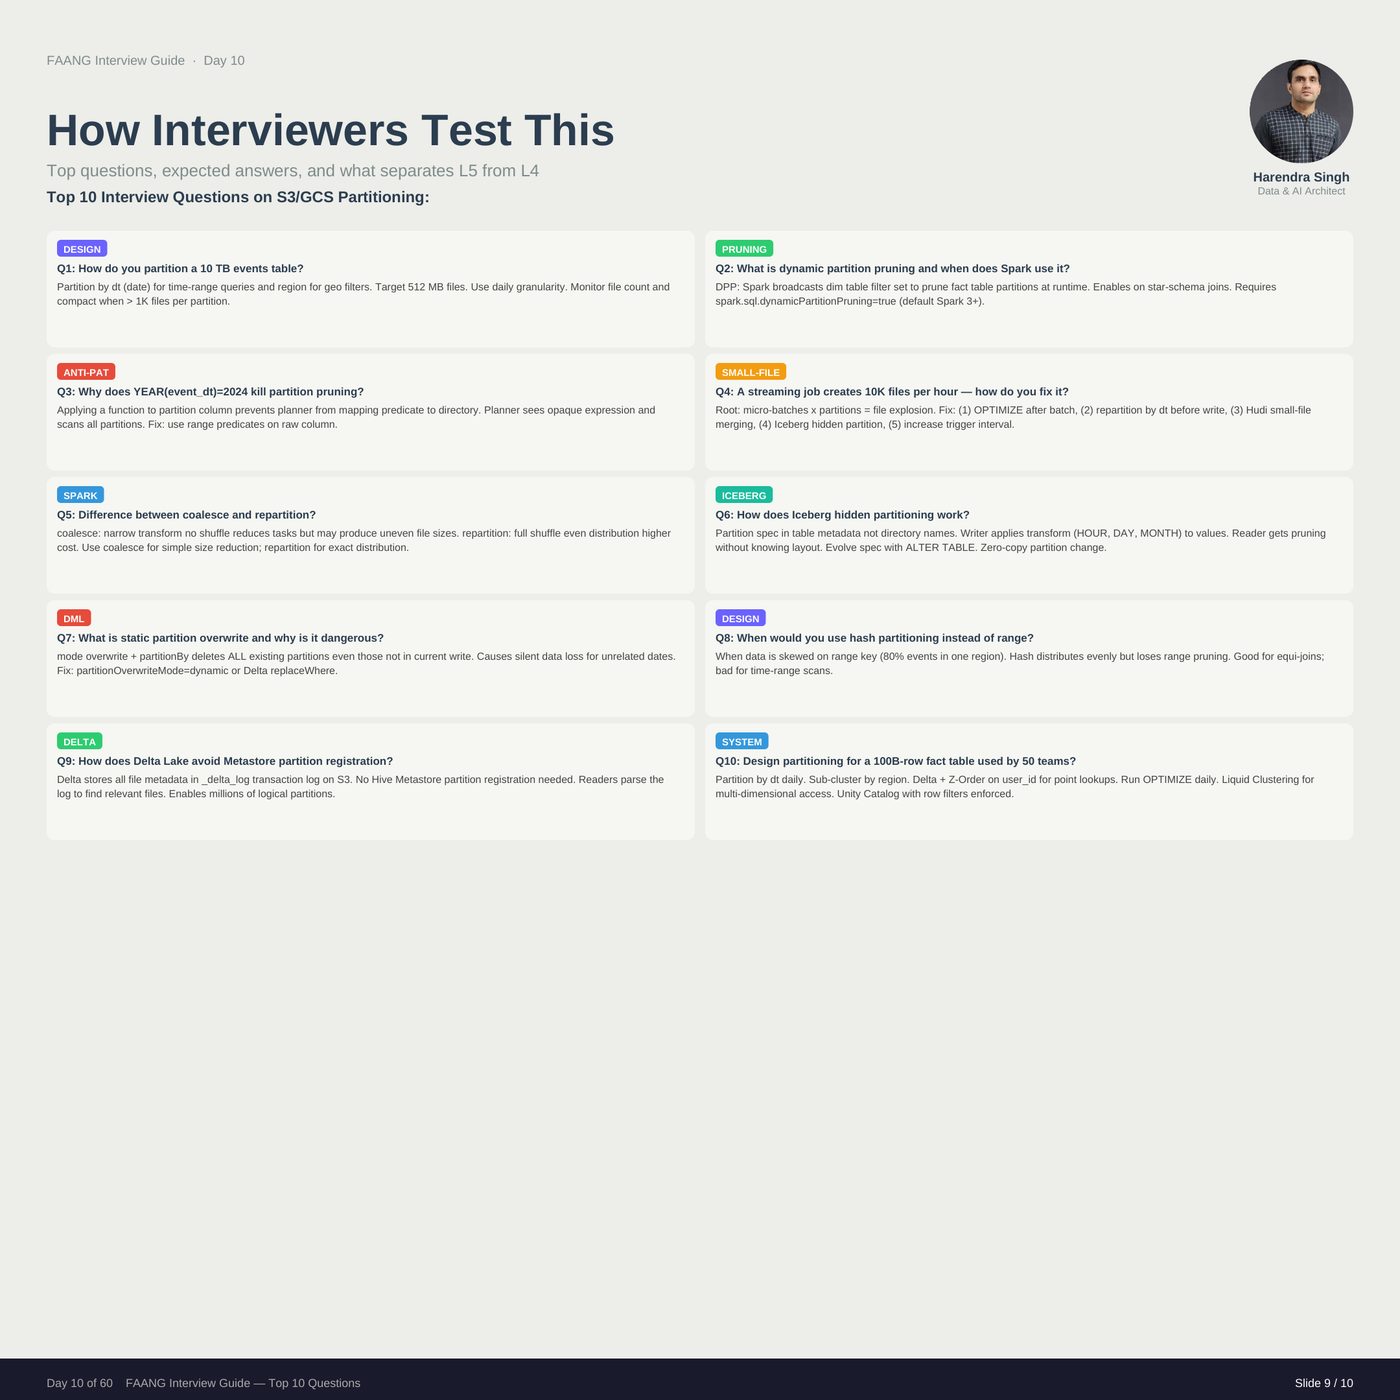
S3/GCS Partitioning Strategies — pruning and the small-file problem
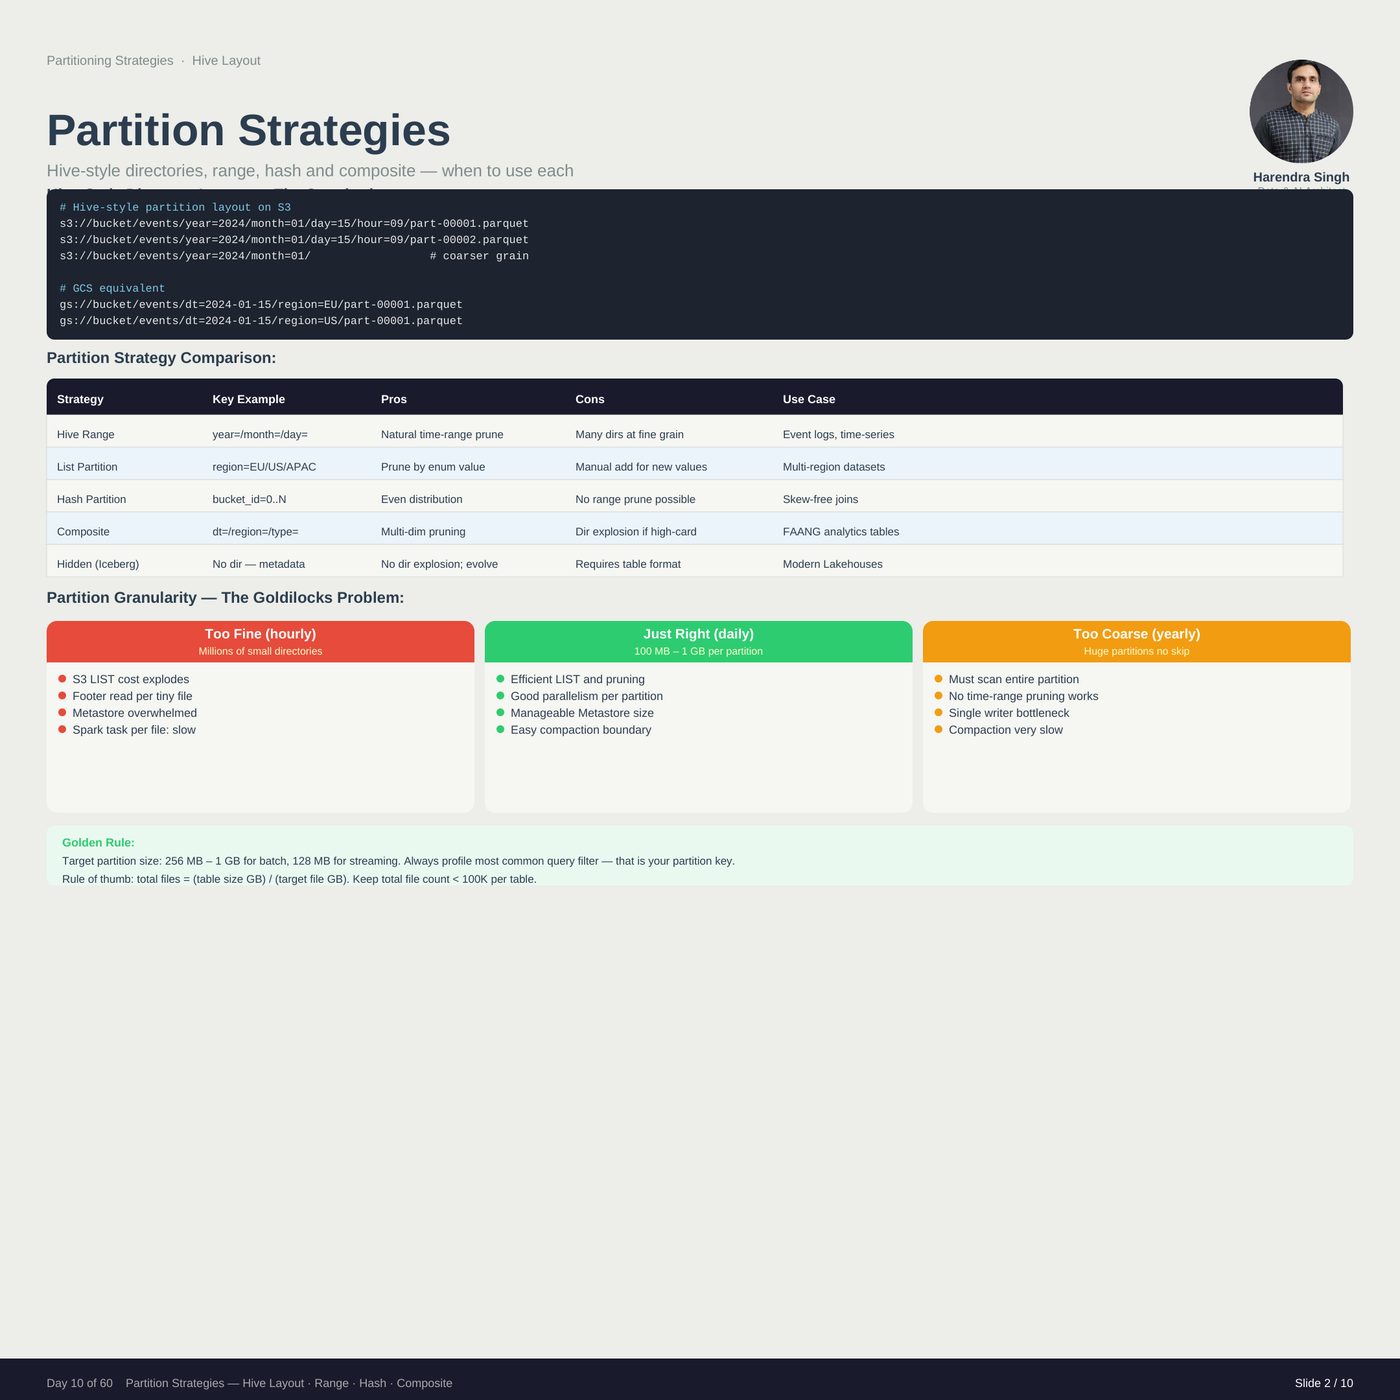
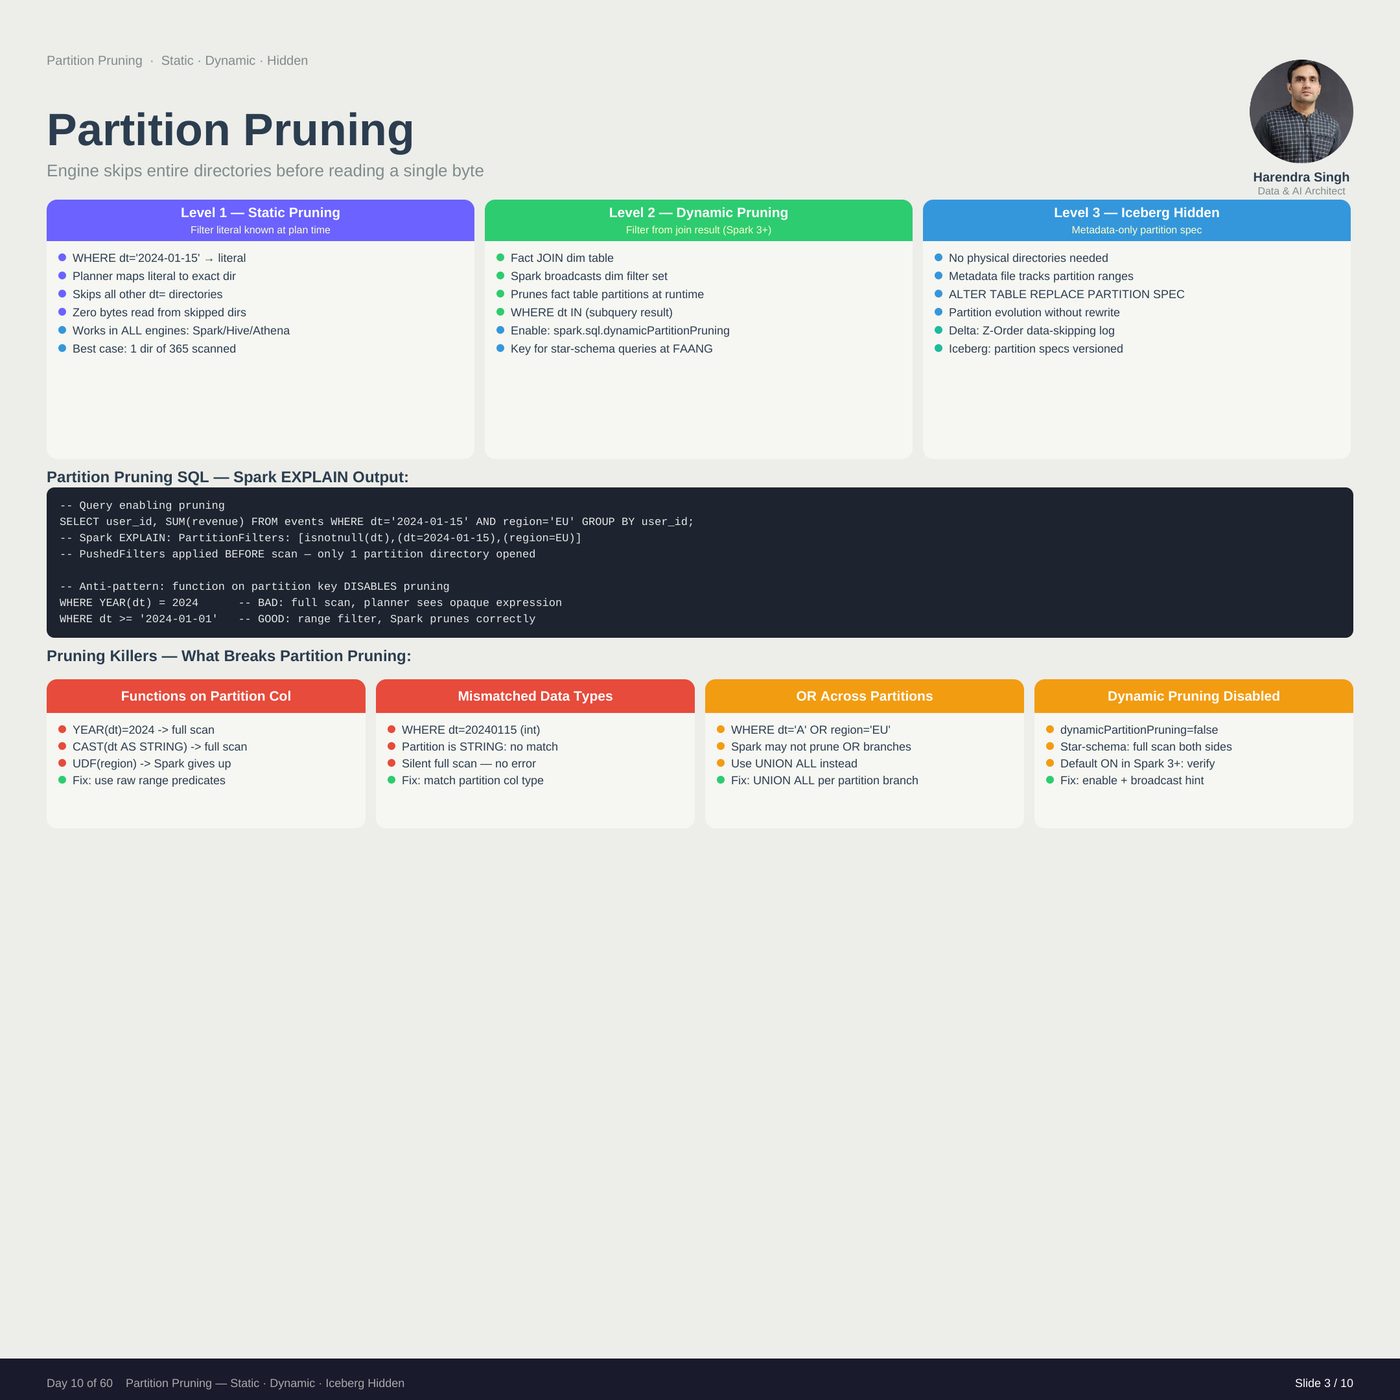
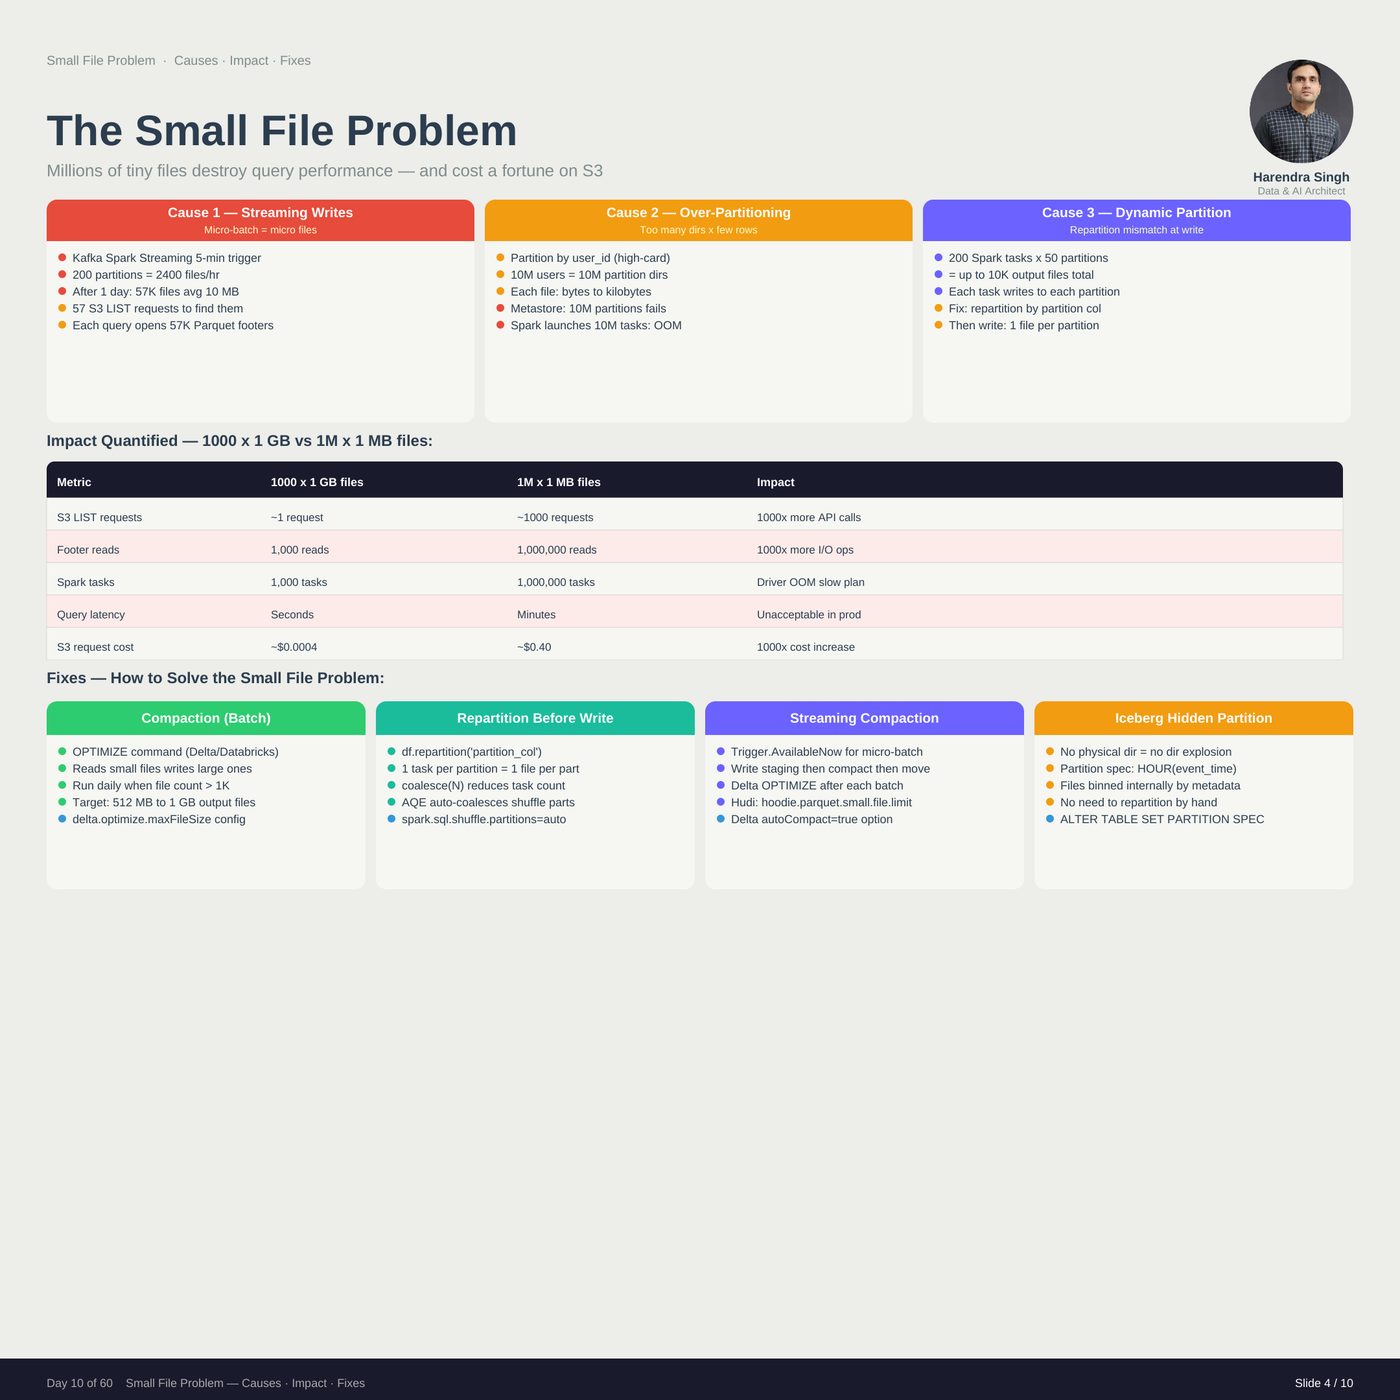
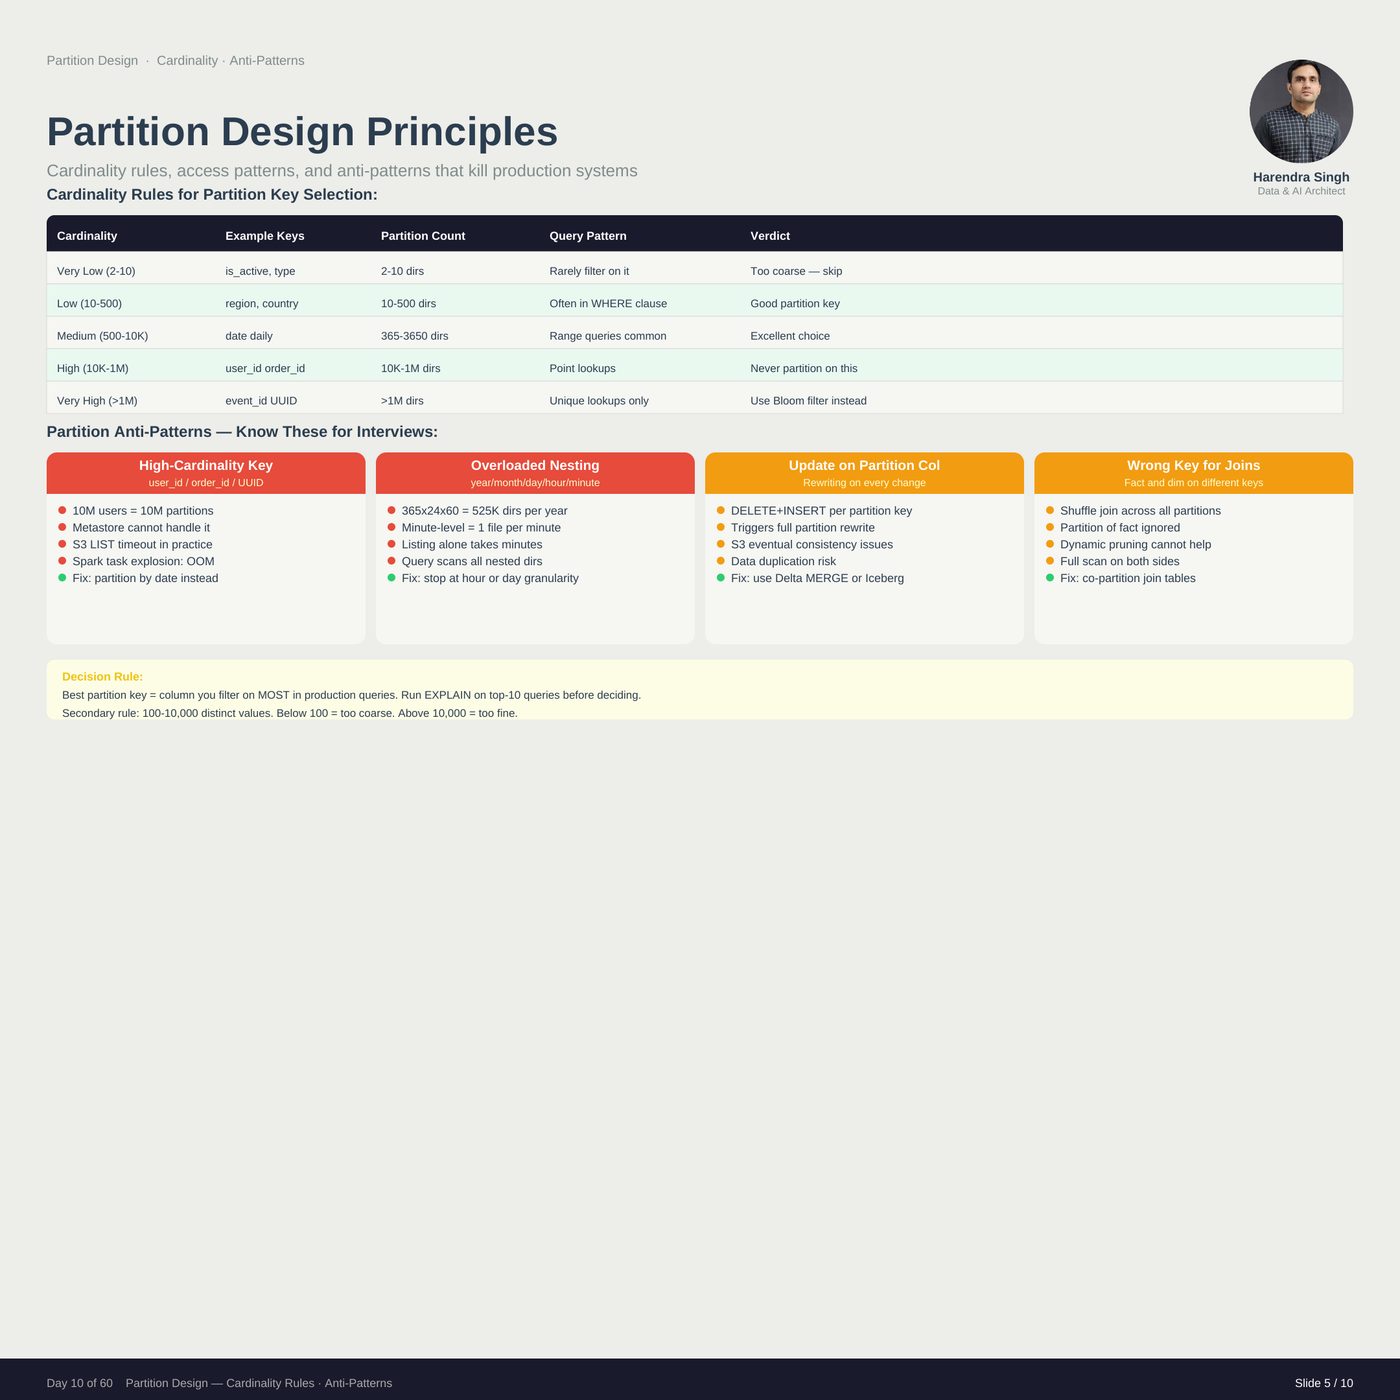
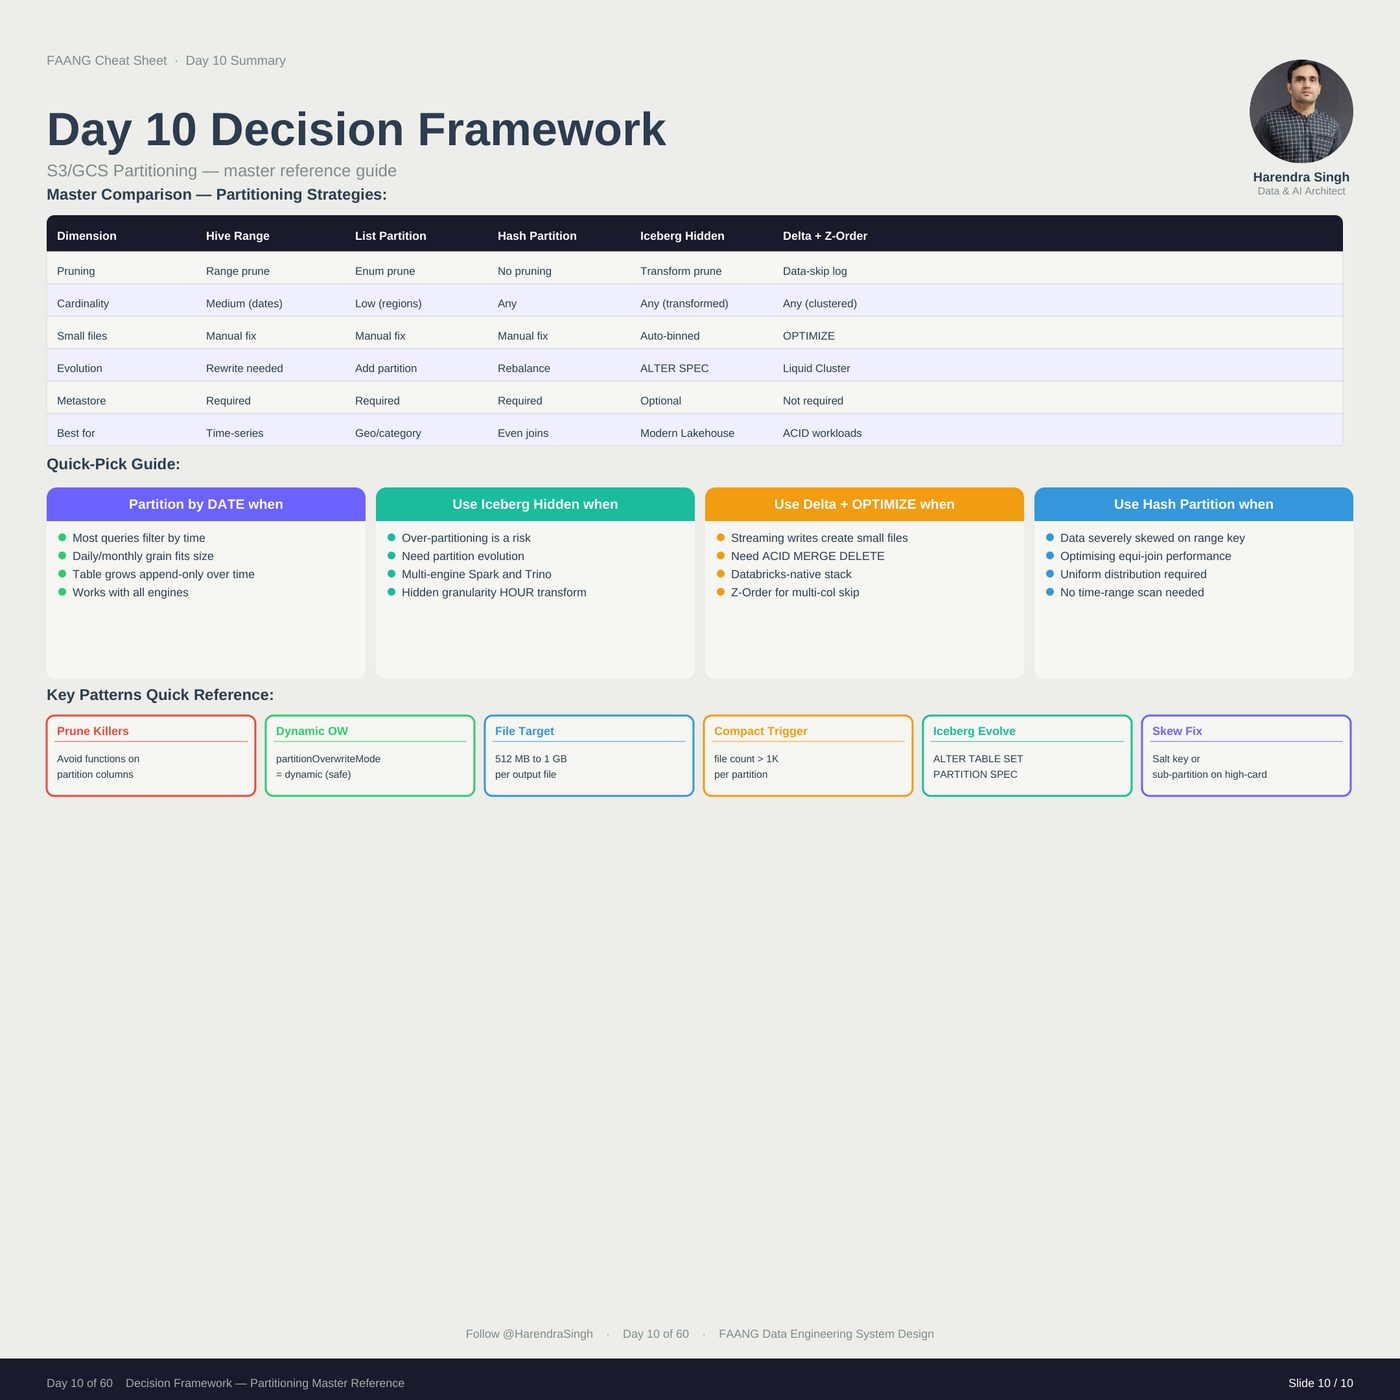
How you lay data out on object storage decides query speed and cost: Hive-style layouts, range vs hash vs composite partitions, pruning and small files.
The trade-off I'd flag
Over-partitioning is the most common mistake on a lakehouse. If a partition holds less than a few hundred MB, you have made the query planner's life harder, not easier.