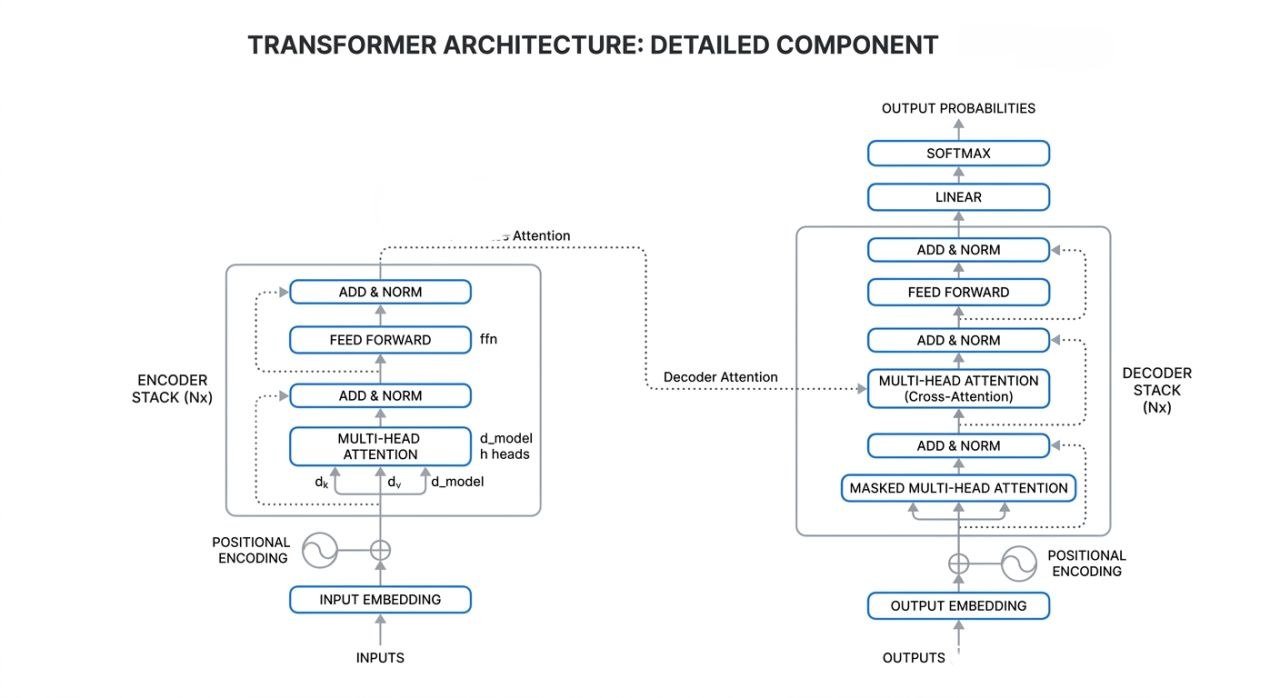
Transformer Architecture — every component, labelled
Encoder and decoder stacks, multi-head attention, feed-forward layers, positional encoding and the output head — the reference diagram.
The trade-off I'd flag
You do not need to retrain a transformer to design around one, but you do need to know why context length and attention cost scale the way they do.