Building Data & AI at Scale
Highly accomplished and results-oriented Solution Architect with 15+ years of experience designing and implementing scalable, AI-powered big data solutions across multi-cloud environments.
Specialised in AI-driven data engineering, leveraging Microsoft Azure, Databricks, Spark, Kafka, Snowflake and Delta Lake to build intelligent pipelines, modern data platforms and real-time analytics systems.
Proficient in architecting AI-enabled automation frameworks for data ingestion, transformation, orchestration and data quality — helping organisations modernise complex data ecosystems and unlock greater operational efficiency.
Strong domain expertise in finance data landscapes, designing high-performance solutions for large-scale, complex datasets with a focus on:
Passionate about emerging AI and data technologies, with a focus on applying Generative AI, LLMs, Agentic AI, Databricks, Spark and Kafka to build the next generation of intelligent, data-driven platforms.
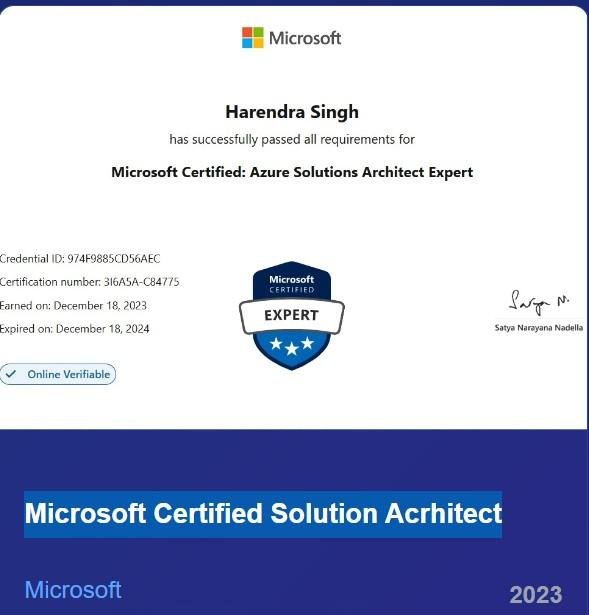
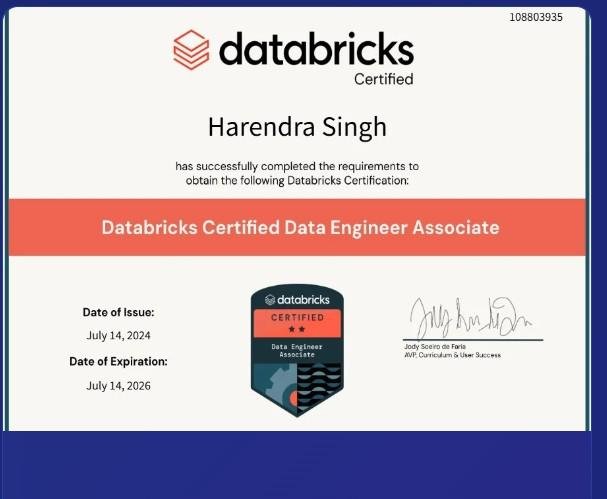
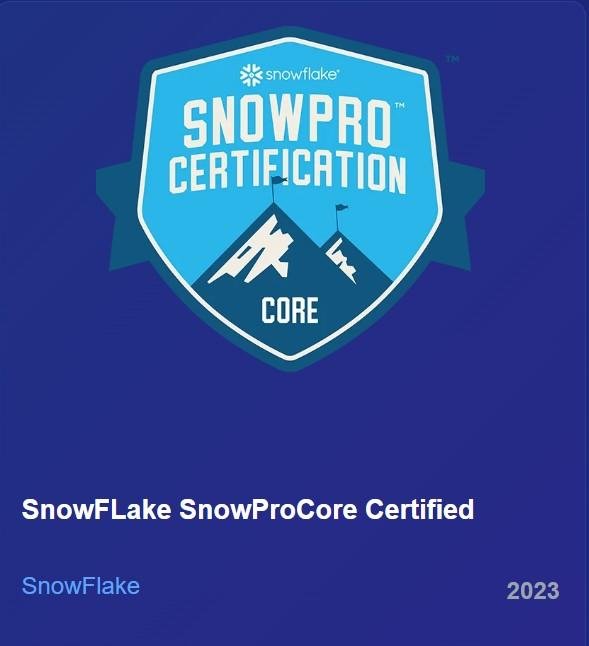
Certified across AWS, Azure, Databricks and Snowflake
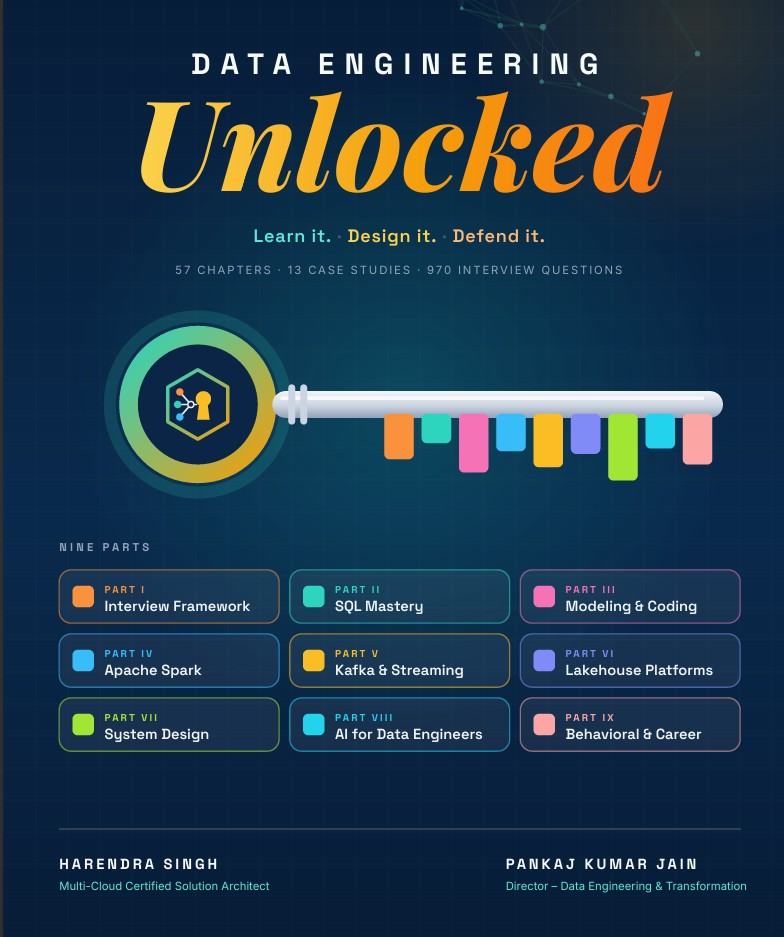
The stack I build with
Pick a category or type to search. Each category links to the diagrams in the library that use it.
Languages
5Big Data & Streaming
8Cloud & Lakehouse
10Architecture & Practices
8AI & GenAI
8Data Security
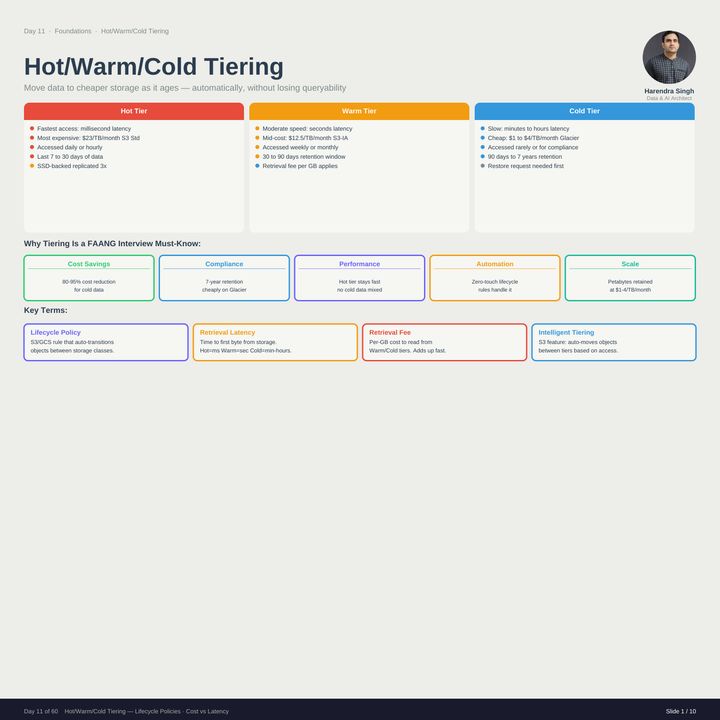
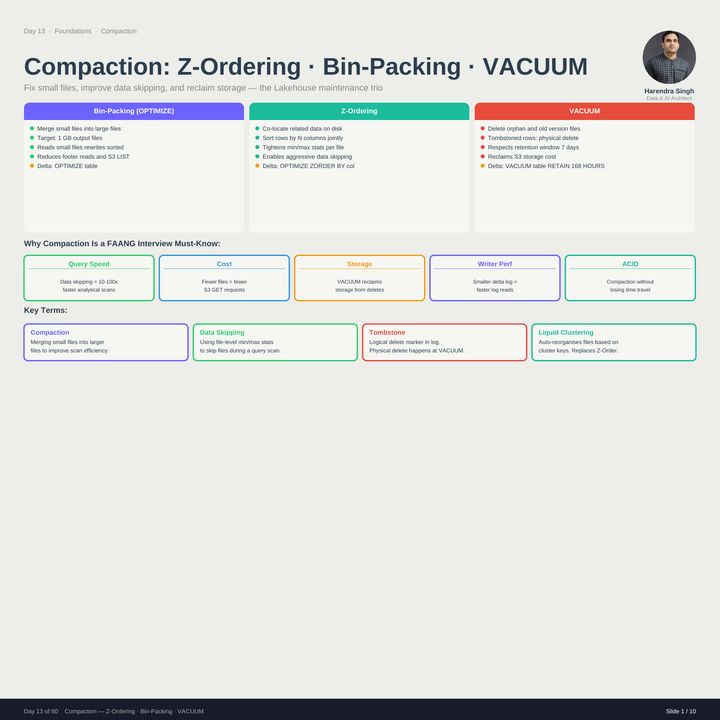
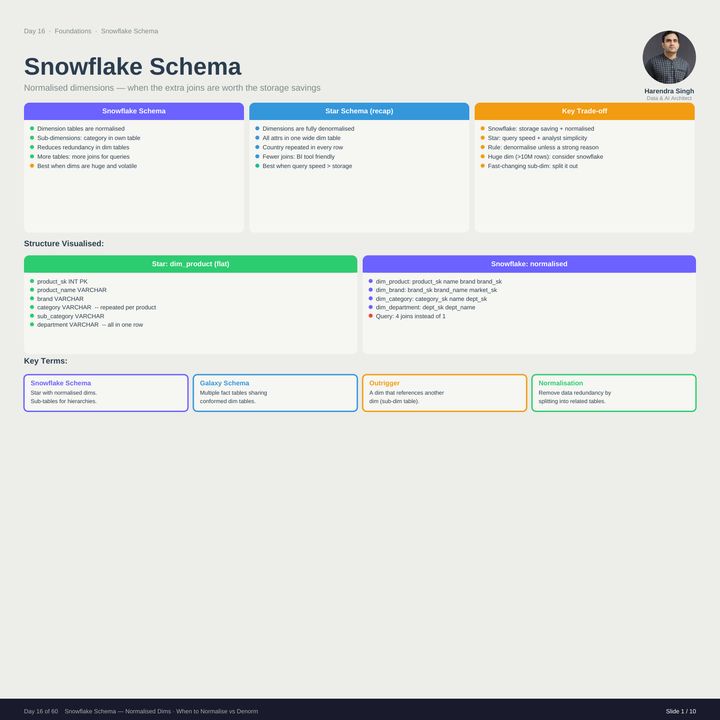
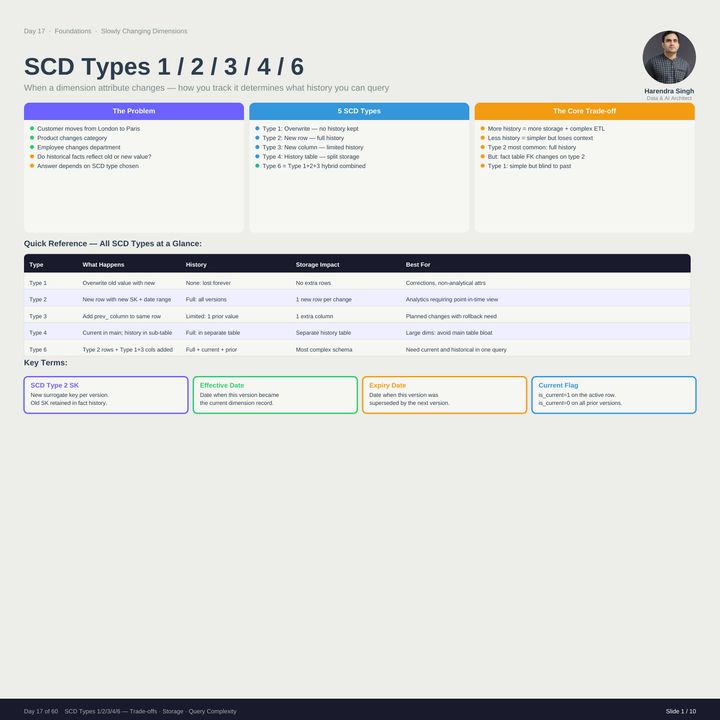
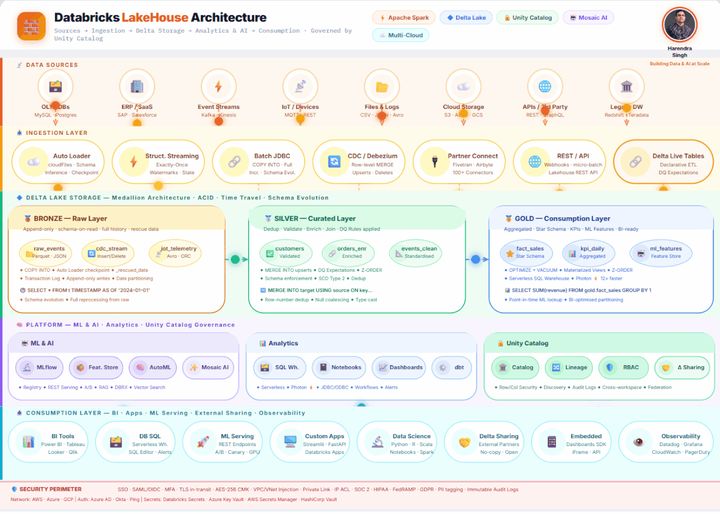
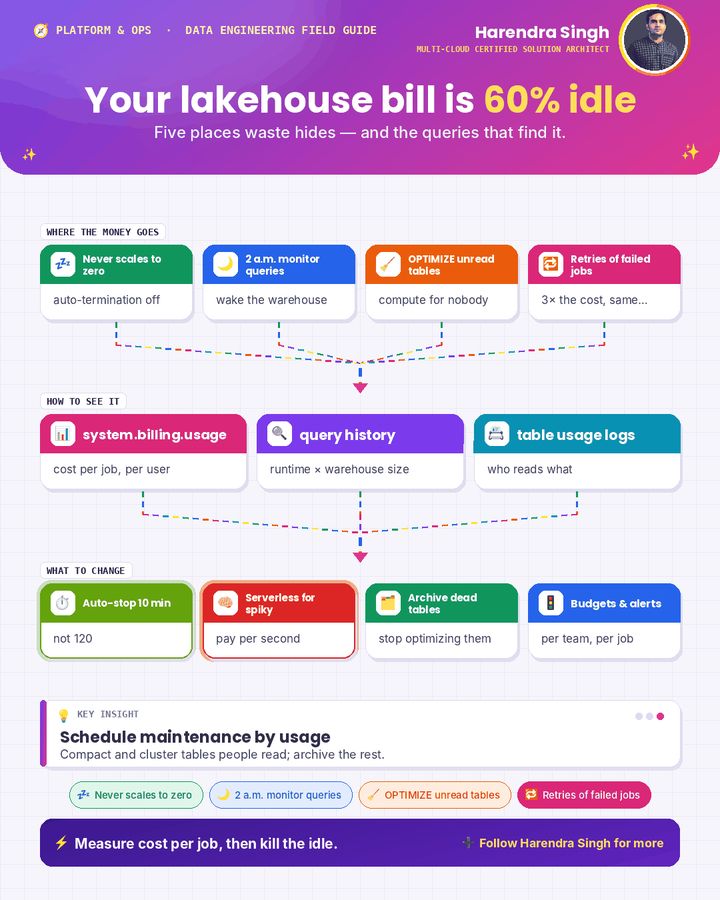
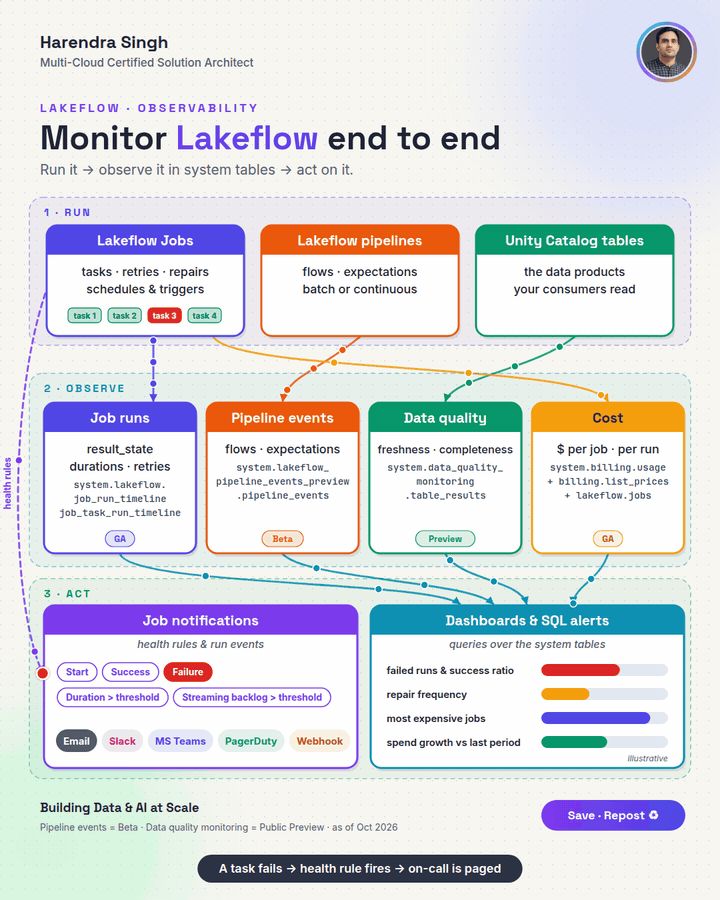
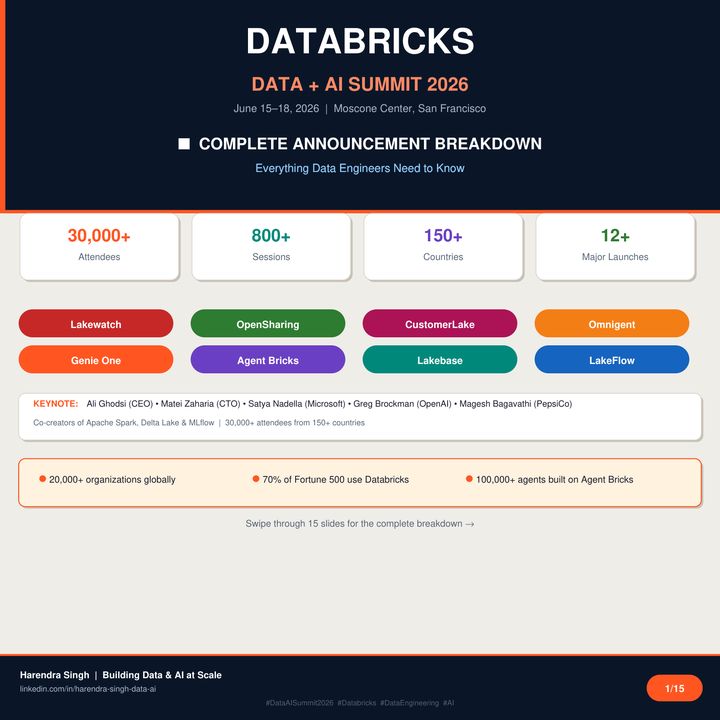
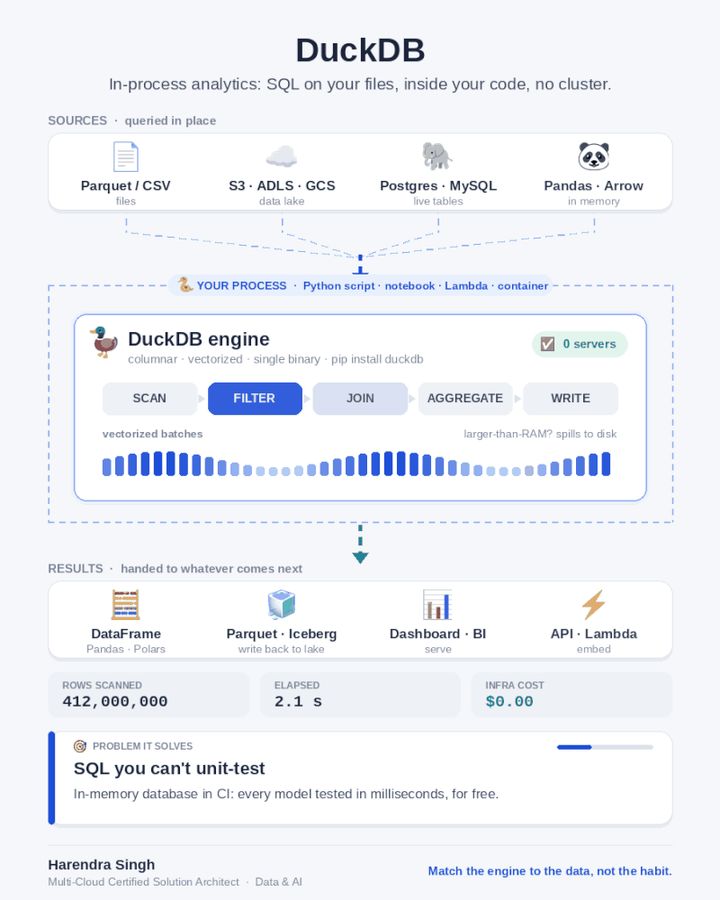
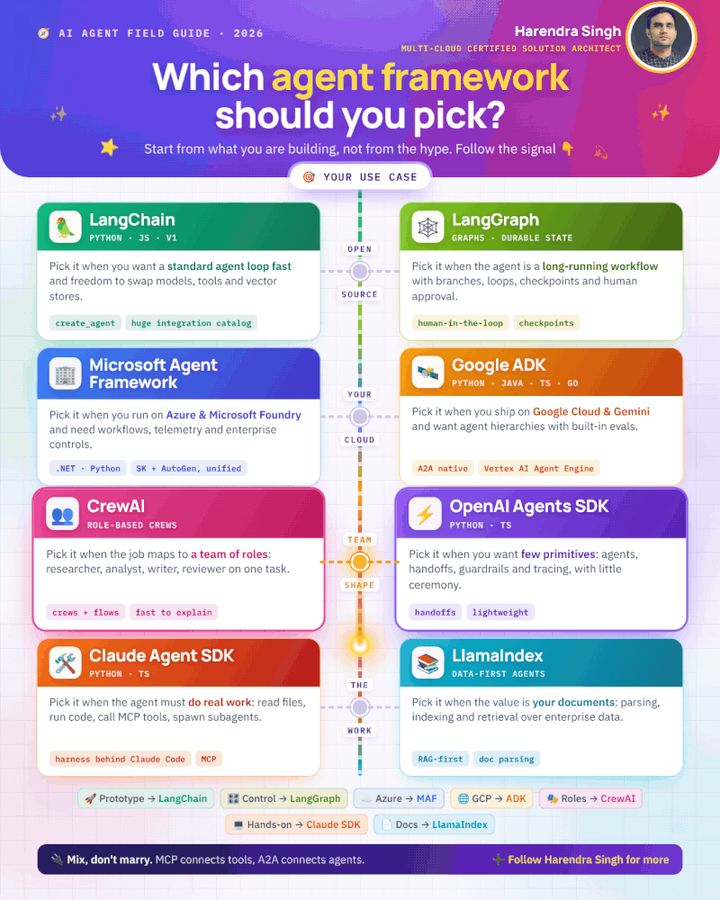
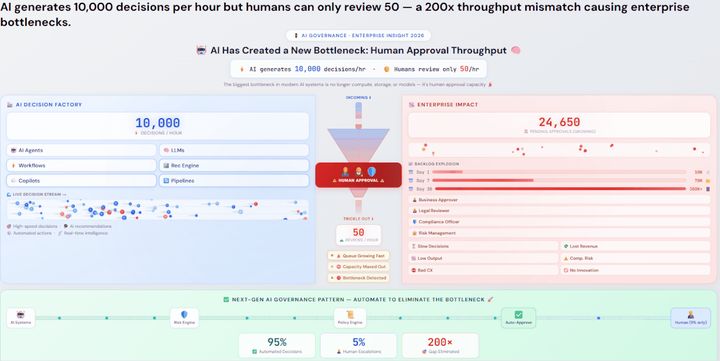
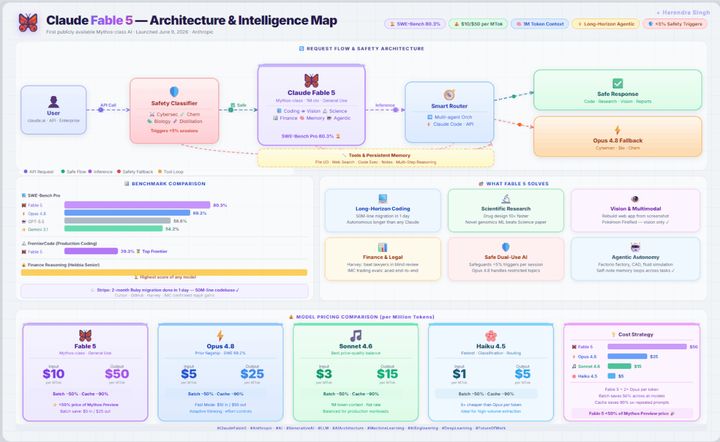
3Five pieces I'd defend in a design review
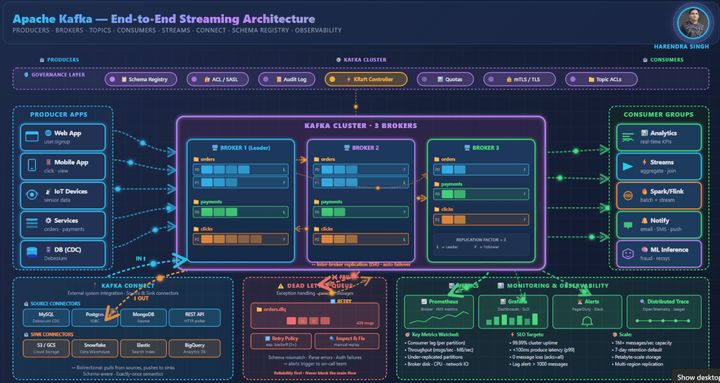 Animated
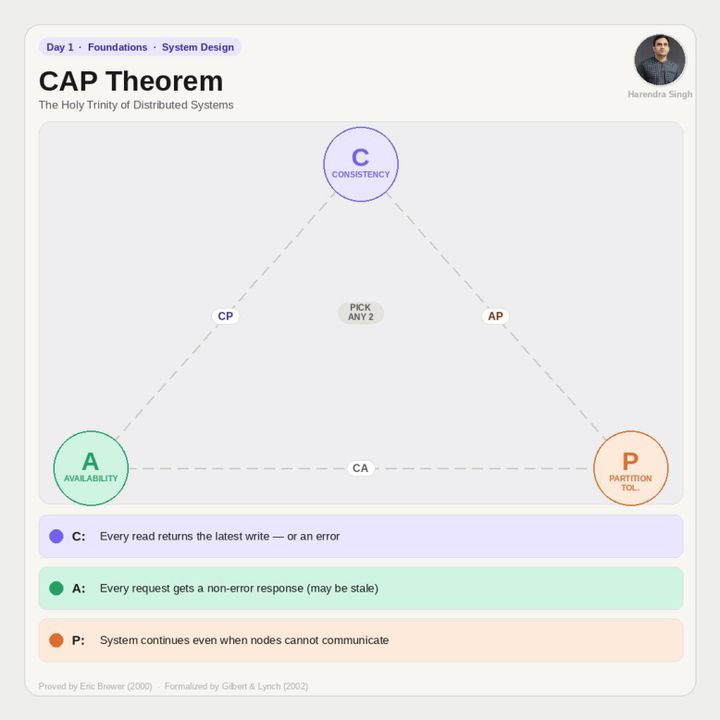 System Design Series · Day 1
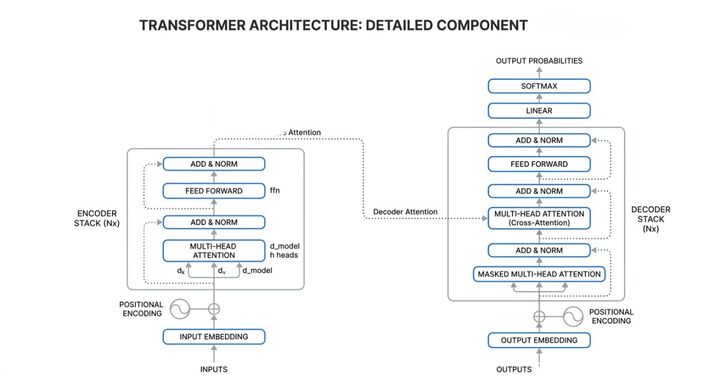
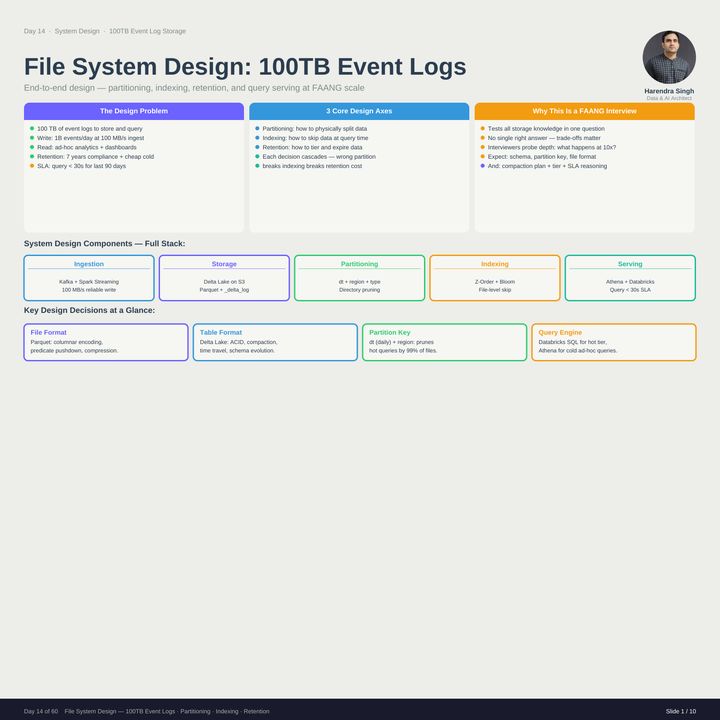 System Design Series · Day 14
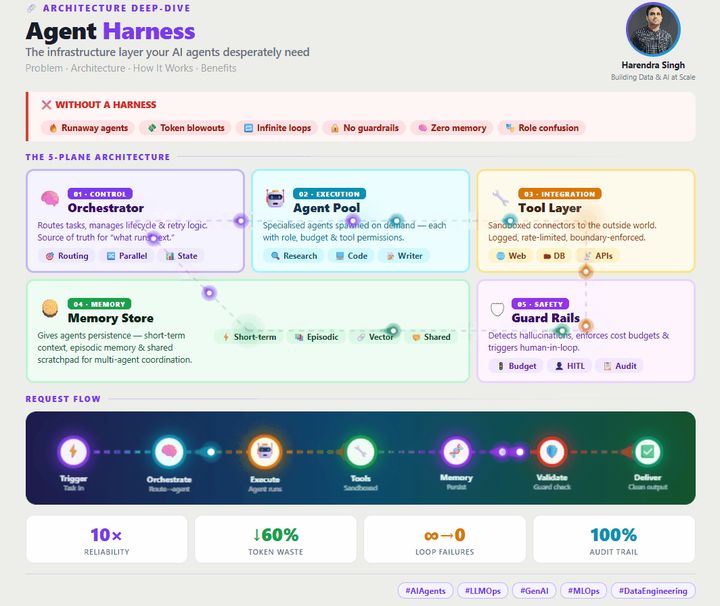 Animated
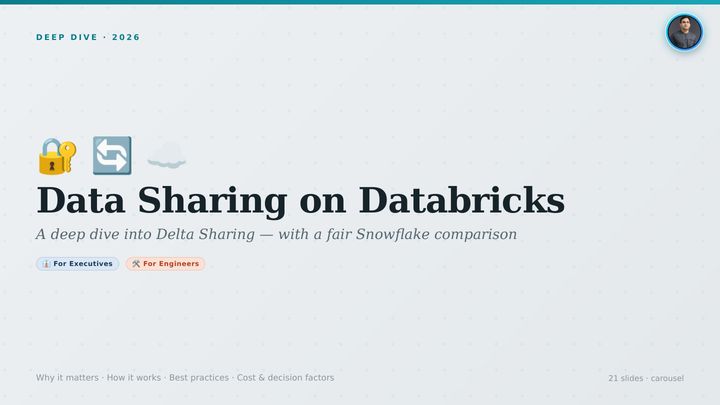
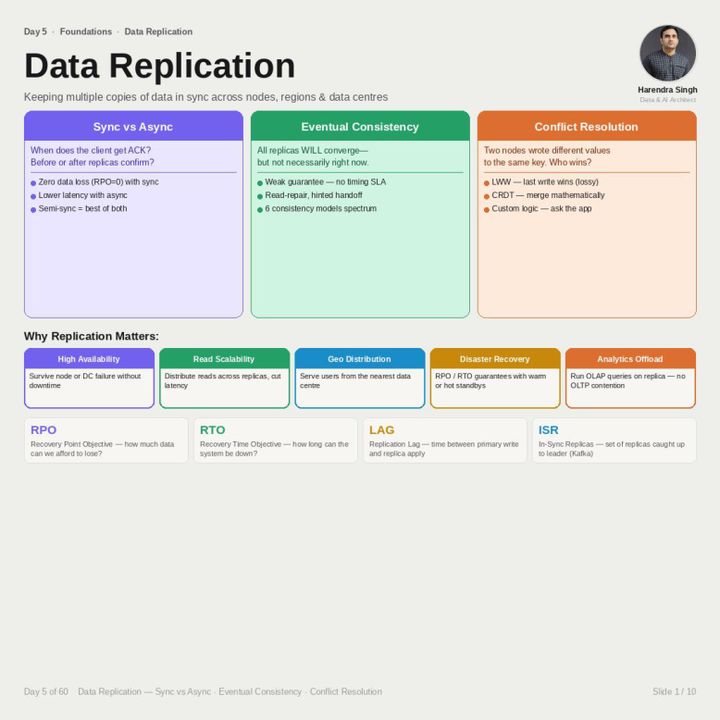
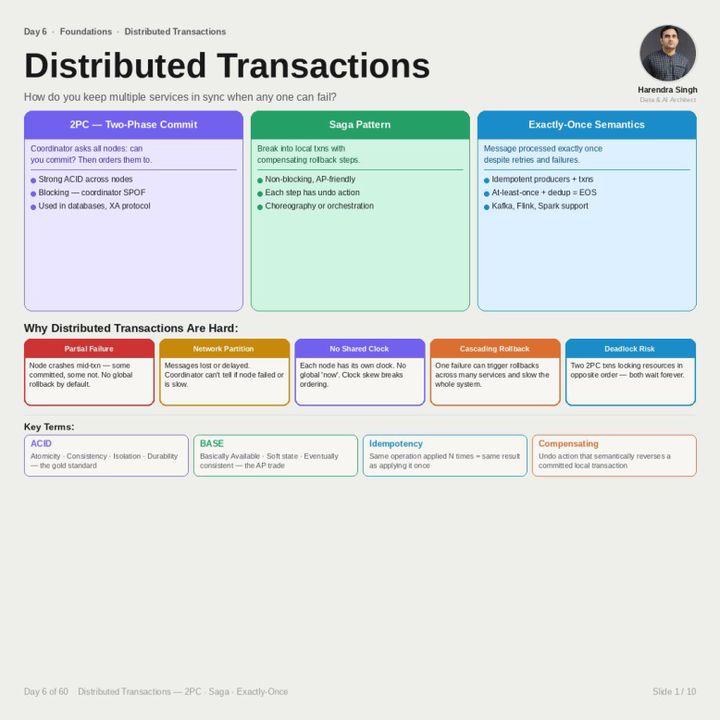
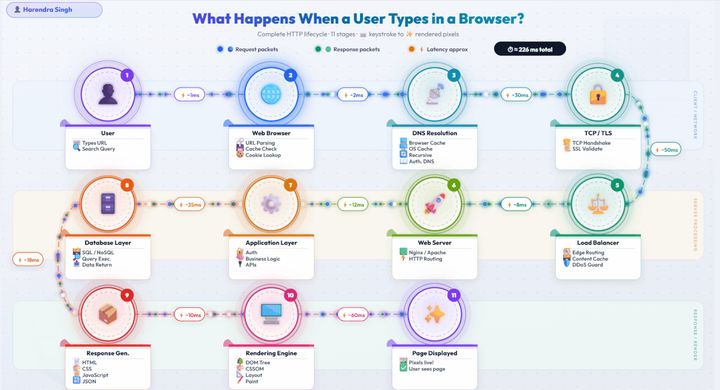
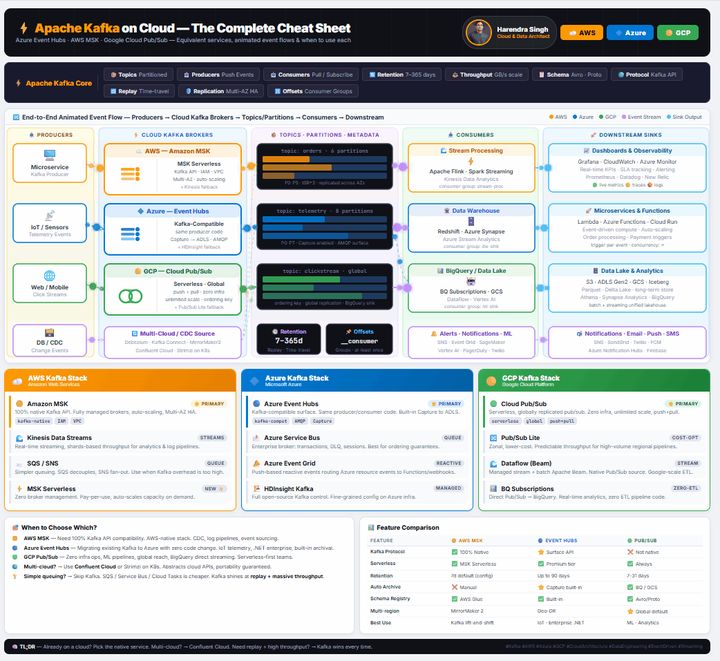
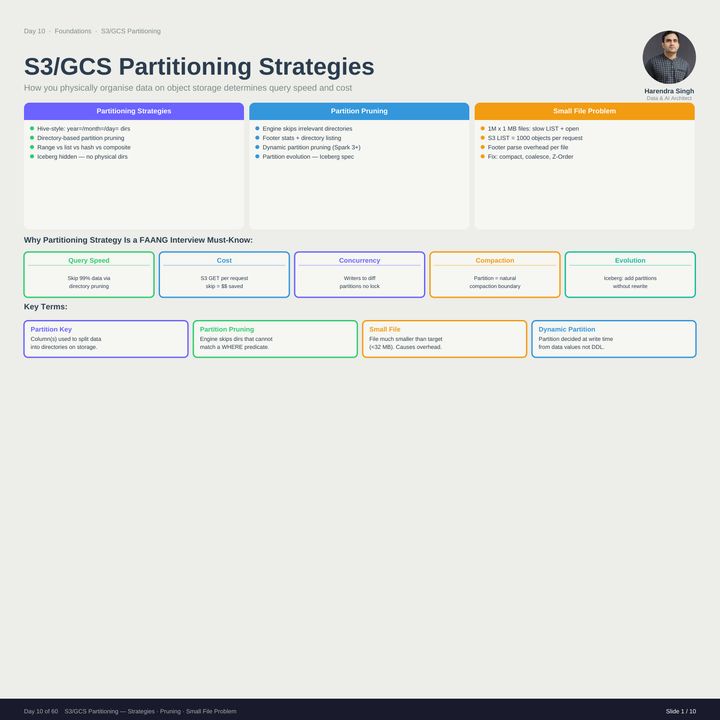
What I've built
Six platforms and tools, from real-time settlement streams to GenAI agents. Pick one to see the problem, what was built and the numbers.
Data Commerce & Consumer 360 Platform
Streaming & lakehouse modernization behind 10+ product teams
Core member of the data engineering team building the shared data backbone for consumer identity, fraud, risk and analytics products — Consumer Keying & Linking, FSBI, Single Auth, Fraud Risk Exchange, Data Panels, Unknown Shoppers and more — at 5B+ records a week.
- Architected the GBS Auth cloud modernization: real-time authorization streams from Cloudera CDP to managed Kafka (AWS MSK, active-active East/West) and Databricks with PySpark Structured Streaming and Lakeflow declarative pipelines — 460M+ transactions a day (~5K TPS) across GBS Auth, GFS Auth and EPOC.
- Built an enterprise Spark ingestion framework that standardised onboarding of core banking (DNA, CTOUCH, Signature, Premier), card (EPOC, Issuer Credit), payments (ACH, Optis) and merchant (DNB, Foursquare, Clover) sources into Azure Data Lake — 5.7B records a week, new-source onboarding 50% faster.
- Automated pipeline delivery end to end with AI-driven orchestration and Databricks Asset Bundles, plus DataOps agents that generate documentation and runbooks so every pipeline ships documented.
Spec-Driven AI Pipeline Framework on Databricks
Define AI workflows through configuration, not custom code
Contributed to the design and implementation of a reusable architecture centred on Specifications, Skills, Prompts and Hooks, so teams configure AI workflows and agents instead of writing bespoke code — a scalable, governed foundation for agentic AI development.
- Designed a specification-driven framework for configuring AI workflows and agents.
- Built reusable Skills, Prompts and Hooks to standardise common AI operations, plus generic instruction templates that accelerate onboarding of new use cases.
- Integrated Databricks Asset Bundles for automated deployment, environment promotion, CI/CD and testing — faster iteration and reliable production rollout.
- Promoted modularity, reusability, governance and observability, significantly shortening the AI application development lifecycle.
Data Quality Agent
Data quality as an automated service, not a manual review
A GenAI-powered agent that profiles ingested tables, runs quality checks and produces a Data Quality Report and an Ingestion Health Report on every run — completeness, freshness, volume, schema drift, duplicates and anomalies. A frontier model then writes plain-English root-cause explanations with recommended fixes, so engineers act instead of investigate.
- Agent-studio design: pluggable agents for profiling, checks, health scoring and recommendations.
- Automated DQ and ingestion-health reports per table, per run, per pipeline.
- LLM-generated fix recommendations — the Spark/SQL change, the config tweak, or the upstream owner — with severity and confidence.
- Model-agnostic: swap Claude, GPT or Gemini without changing the agents. Built for the lakehouse: Spark, Delta Lake, Unity Catalog.
Pipeline Onboarding Automation — df-pipeline-studio
A standardised, documented pipeline on day one
A studio that automates the slow part of pipeline engineering: onboarding. It takes a new source through job onboarding, JSON pipeline-profile generation, automated EDA on the source data and runbook / documentation generation ready for Confluence — built the same way every time.
- Onboarding wizard: source → config → job profile, no boilerplate.
- Automated EDA: profiling, column classification, key and relationship discovery.
- Generates Databricks job profiles, runbooks and pipeline docs from the same metadata; GenAI-assisted documentation that stays in sync with the config.
- Consistent patterns across every onboarded pipeline.
Card Console Management
Real-time cardholder events for financial-institution clients
Architected and developed a highly scalable Spark Streaming end-to-end pipeline processing real-time cardholder events, with disaster recovery serving multiple business units.
- End-to-end streaming solution on Hadoop, Spark, Kafka, Oracle GoldenGate for Big Data and Azure SQL Database.
- Deployed Oracle Big Data Adapter for real-time ingestion from the Tandem system into Kafka.
- Implemented disaster recovery for Spark Streaming applications with Kafka SRM (Streams Replication Manager).
- Built a Kafka data-parsing and validation utility — 5% less effort in testing and validation across teams.
Debit Card Modernization
Mission-critical debit data architecture for real-time settlement
Led the design and development of an end-to-end debit data architecture on the big-data ecosystem to handle real-time settlements for banking clients.
- Developed Spark and Kafka Structured Streaming consumer applications for debit data processing.
- Set up and configured Kafka clusters, topics and partitioning strategy for high-throughput debit workloads.
- Designed a reusable Tandem-to-Kafka real-time ingestion utility with Oracle Big Data Adapter — 50% less development effort and 5% cost savings, adopted by multiple business units.
Let's talk systems
Architecture reviews, speaking, mentoring, or a role where the data platform is the product.
Send me a quick note and I'll reply with the PDF
I share my résumé with recruiters and hiring managers on request. Use whichever is easiest:
hello@harendrasingh.comSuggested subject: Résumé request — [your company]
Tell me what you need and I'll send it over
The PDFs, GIFs and the book sample from the library are shared on request. Use whichever is easiest:
hello@harendrasingh.comSuggested subject: Download request — [item name]